One allowlist entry short, four applications broken
Four ArgoCD Applications failed, and only one of the four errors named the real cause. The others pointed confidently at the wrong layer — and the eventual fix meant admitting that a security control I had written could not survive contact with the thing it was protecting.
I applied the root app-of-apps. Eight Applications, ordered by sync wave. Four of them failed.
NAME                   SYNC STATUS   HEALTH STATUS
istio-traffic          Synced        Healthy
logging                Unknown       Unknown
observability          Unknown       Unknown
observability-config   OutOfSync     Missing
promtail               Unknown       Unknown
root                   Synced        Healthy
secrets                Synced        Healthy
webapp                 OutOfSync     Healthy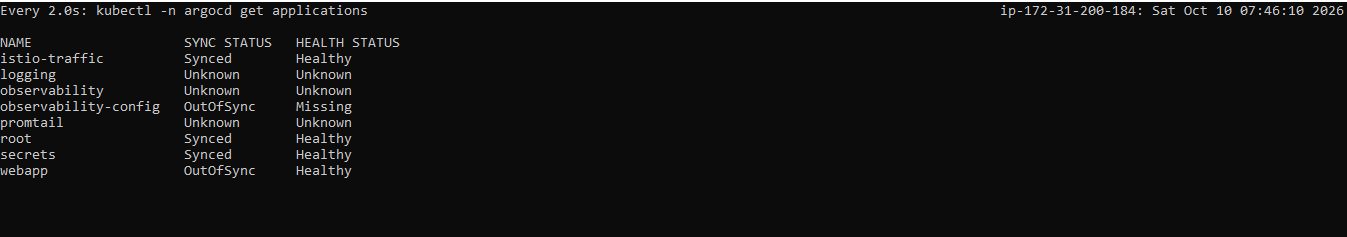
Unknown, one Missing. And istio-traffic — the last wave — reporting Synced and Healthy while the waves before it are refused. That detail gets its own section below.Two different failure modes, and the one that mattered was the quieter of them.
Only one error named the cause
observability, logging and promtail said this:
[InvalidSpecError] application repo
https://prometheus-community.github.io/helm-charts
is not permitted in project 'platform'
Clear enough. My AppProject had one entry under sourceRepos — the GitOps repository — with a comment I was rather pleased with at the time:
sourceRepos:
  - https://github.com/Syed-Amjad/platform-gitops.git  # this repo, and only this repo
Three Applications are multi-source: they pull a chart from an upstream Helm repository and their values from mine. Those upstreams were not on the list.
But observability-config and webapp said something else entirely:
failed to discover server resources for group version
monitoring.coreos.com/v1: the server could not find the requested resource
That is a CRD error. It points at kube-prometheus-stack, or at a sync-wave ordering problem, or at a malformed PrometheusRule. It points anywhere except an RBAC allowlist two layers upstream.
Debugging from the last error would have led into chart internals and found nothing wrong there — because nothing was wrong there.
Fixing the first thing did not fix it
I added the two upstream repositories. The three Unknown Applications moved to OutOfSync — progress: they could now be read — and then failed on the AppProject’s other gates:
namespace kube-system is not permitted in project 'platform';
resource apiextensions.k8s.io:CustomResourceDefinition is not permitted;
resource rbac.authorization.k8s.io:ClusterRole is not permitted;
resource rbac.authorization.k8s.io:ClusterRoleBinding is not permitted;
resource admissionregistration.k8s.io:MutatingWebhookConfiguration is not permitted
kube-prometheus-stack creates Services in kube-system so that Prometheus can scrape the control plane — CoreDNS, the scheduler, the kubelet. It ships its own CRDs. Its operator needs cluster RBAC and admission webhooks.
My project allowed two cluster-scoped kinds and explicitly denied ClusterRole and ClusterRoleBinding, under this comment:
# Privilege escalation via a committed manifest is the GitOps-specific
# attack, and this is the control.
That reasoning is correct. It is also incompatible with installing a monitoring operator through GitOps.
There is no clever resolution
I looked for one. There isn’t.
A platform that installs an operator through GitOps is a platform whose repository can create cluster RBAC. The choices are:
| Option | Cost |
|---|---|
| Widen the AppProject | The repository can now create ClusterRoles |
| Install the stack outside GitOps | Nothing reviews it at all |
| Do not deploy it | No observability |
I widened it, and changed the comment to describe the control that actually exists rather than the one I wished existed. What still constrains the project:
sourceRepos— three named repositories, not'*'destinations— five namespace entries, one of them thewebapp-*pattern, not'*'clusterResourceWhitelist— an allowlist of kinds, so a manifest introducing something new is still refused
What no longer constrains it: it can create ClusterRoles. That is written in the file now. It also raises the stakes on everything that can write to the repository — including the CI token that commits image tags into it.
I also removed ClusterRole and ClusterRoleBinding from namespaceResourceBlacklist, where I had originally put them. They are cluster-scoped, so that field was never the one governing them — it had been decorative the whole time.
The waves did not wait
Look at the status table again. istio-traffic is wave 4, and it reached Synced and Healthy while waves 1 and 2 were still being refused.
Sync waves order creation. An Application that fails validation sits in Unknown — and Unknown does not block the next wave the way Progressing does. The ordering this platform leans on is weaker than its own README implied, and that is worth knowing before relying on it for anything that must not start early.
A bonus: ArgoCD will not retry
After fixing the project, nothing happened for ten minutes. It looked slow. It had given up:
Skipping auto-sync: failed previous sync attempt to [65.1.1 cf80f8e…]
and will not retry for [65.1.1 cf80f8e…]
ArgoCD does not retry an automated sync on a revision that already failed. Sensible — it avoids a hot loop — but it means “wait and see” is not a strategy. Either push a new commit, changing the revision, or trigger a sync explicitly.
What I took from it
- Debug from the first error, not the loudest one. Three of my four messages were downstream symptoms describing the wrong layer with total confidence.
- A cascade has one cause and many victims. Count the distinct error texts before you start. Two different messages across four failures told me there were two layers to this, not four problems.
- Fixing the first cause reveals the second. The allowlist needed widening twice, in two different fields, and the second only became visible once the first was done.
- Write comments that describe the control you have. “This repo, and only this repo” was accurate when written and false within a day. A comment asserting a guarantee you have since removed is worse than no comment.
- When a security boundary blocks a legitimate need, say which one you loosened. The honest version — “this project can create cluster RBAC, and here is what still constrains it” — is more useful than quietly deleting a line.
- “Nothing is happening” is a state worth checking. Idle is not always slow. Sometimes the controller has made a decision and logged it.
From the GitOps delivery platform build.
References
- Argo CD: projects —
sourceRepos,destinations, and the cluster-resource allow and deny lists. - Argo CD: sync phases and waves
- Argo CD: automated sync semantics — “Automatic sync will not reattempt a sync if the previous sync attempt against the same commit-SHA and parameters had failed.”
- kube-prometheus-stack chart — the CRDs, RBAC, webhooks and
kube-systemServices it installs. - Kubernetes: RBAC — why the ability to create ClusterRoleBindings is the ability to own the cluster.