Built and operated in a production environment. Architecture and design decisions are described generically — no customer identifiers, addresses, or schema details are published. The screenshots are real, with addresses and host names redacted.
The problem
Managing host firewall rules across a large Linux estate by hand does not scale, and it fails in a specific way: the rules drift. Every one-off exception someone adds during an incident becomes permanent, because nobody remembers to remove it. Over time the firewall stops describing intent and starts describing history.
The three questions that become impossible to answer are always the same:
- Why does this rule exist?
- Who approved it, and when?
- Is it still needed?
What I built
A policy-as-code system for network access control. A central database holds the declared intent; a Python generator compiles per-host rulesets from it; an orchestrator distributes and applies them with safety controls at every step.
Declarative source of truth
Access is expressed as data, not as configuration files. Role-tiered groups — administrative, management, engineering, service-consumer — each carry a defined port set. Membership changes are data changes; capability changes require review. That separation makes the common operation safe and the rare operation deliberate.
Time-boxed exceptions
One-off grants live in an exception table with an expiry timestamp. An expired grant simply stops being emitted on the next generation — no human action, no ticket, no reminder.
This is the part auditors care about most. Most firewall exception processes depend on somebody remembering to revoke access. This one expires by default.
Shell access is deliberately excluded from the exception mechanism entirely. SSH can only ever be granted through the curated role tiers, which puts a hard boundary against privilege escalation via a single database row.
Safe deployment
Applying a firewall ruleset remotely is one of the few operations that can permanently disconnect you from the machine you’re changing. The deployment path is built around that risk:
- Automatic backup of the existing ruleset before any change
iptables-restorevalidation before commit- Rollback protection on failure
- Post-apply verification
- A protected administrative access rule that sits outside the generated policy, so no regeneration can remove it
- A single-instance lock, so two runs can never apply at the same time
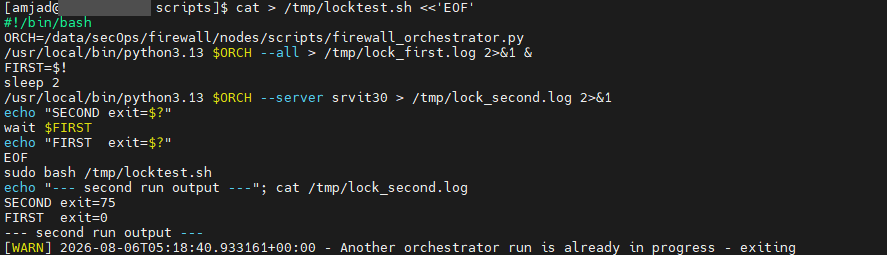
75 without touching anything, and the first completes normally. Two processes applying rulesets to the same host at once is exactly the kind of accident that ends in a lockout. (Control-node host name redacted.)IPSet migration
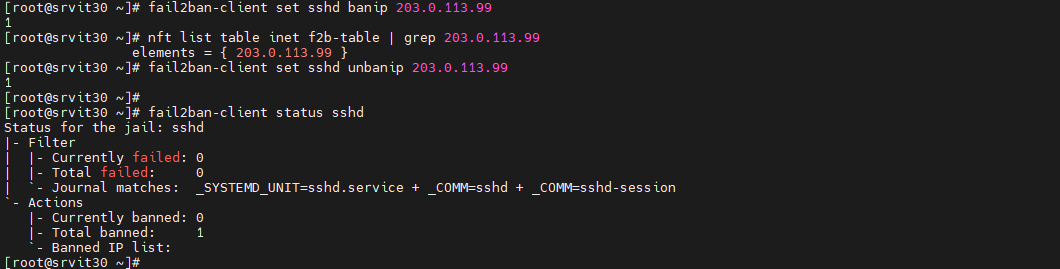
Blocklists originally meant one iptables rule per address, evaluated linearly on every packet. Migrating to IPSets replaced N rules with a single rule and an O(1) hash lookup — and, more importantly, made membership changes take effect immediately without reloading the ruleset at all.
Results
| Measure | Before | After |
|---|---|---|
| Per-server deployment time | ~16s | ~4–5s |
| Large-scale deployment | baseline | 3× faster |
| Blocklist rule evaluation | O(n) linear | O(1) hash |
| Blocking an address | ruleset reload | immediate, no reload |
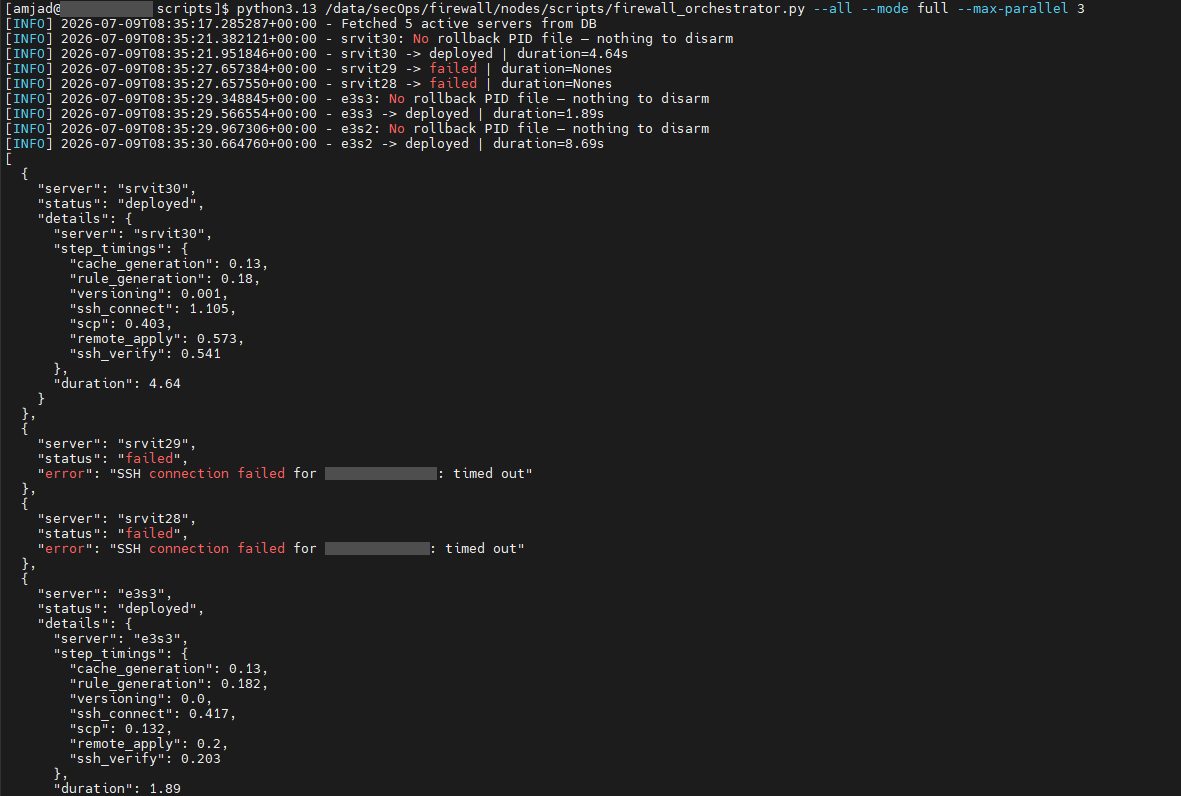
Alongside the platform: default-deny policies, SSH hardening, brute-force protection and DDoS mitigation rolled out across the managed fleet.
The reboot that silently removed the firewall
The worst defect in the platform was not in the generator or the deployment path. It was at boot.
On these hosts, the distribution’s own ipset and iptables restore units were enabled and symlinked — and never ran. They hang off network-pre.target, which never activated here. systemctl reported them enabled and inactive: no error, no failed unit, nothing in any log. The firewall simply did not come back after a reboot.
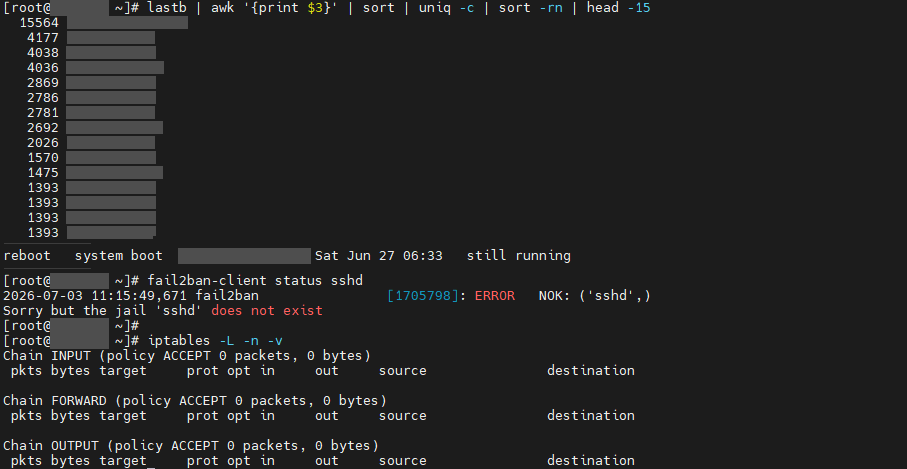
ACCEPT. It had been running the generated ruleset; after the reboot, it had nothing. (Addresses, host name and kernel version redacted.)The fix keeps the standard iptables.service name, so operators and other tooling still find it where they expect, but overrides it with a unit wired the way Fail2Ban’s is — WantedBy=multi-user.target, After=network.target — which does start at boot on these hosts. One script restores the IPSets and then loads the ruleset, in a single process, so the ordering needs no dependency between services. A @reboot cron entry is an independent backup.
The order matters: a rule that matches against an IPSet cannot load if the set does not exist yet, and one missing set fails the whole ruleset.
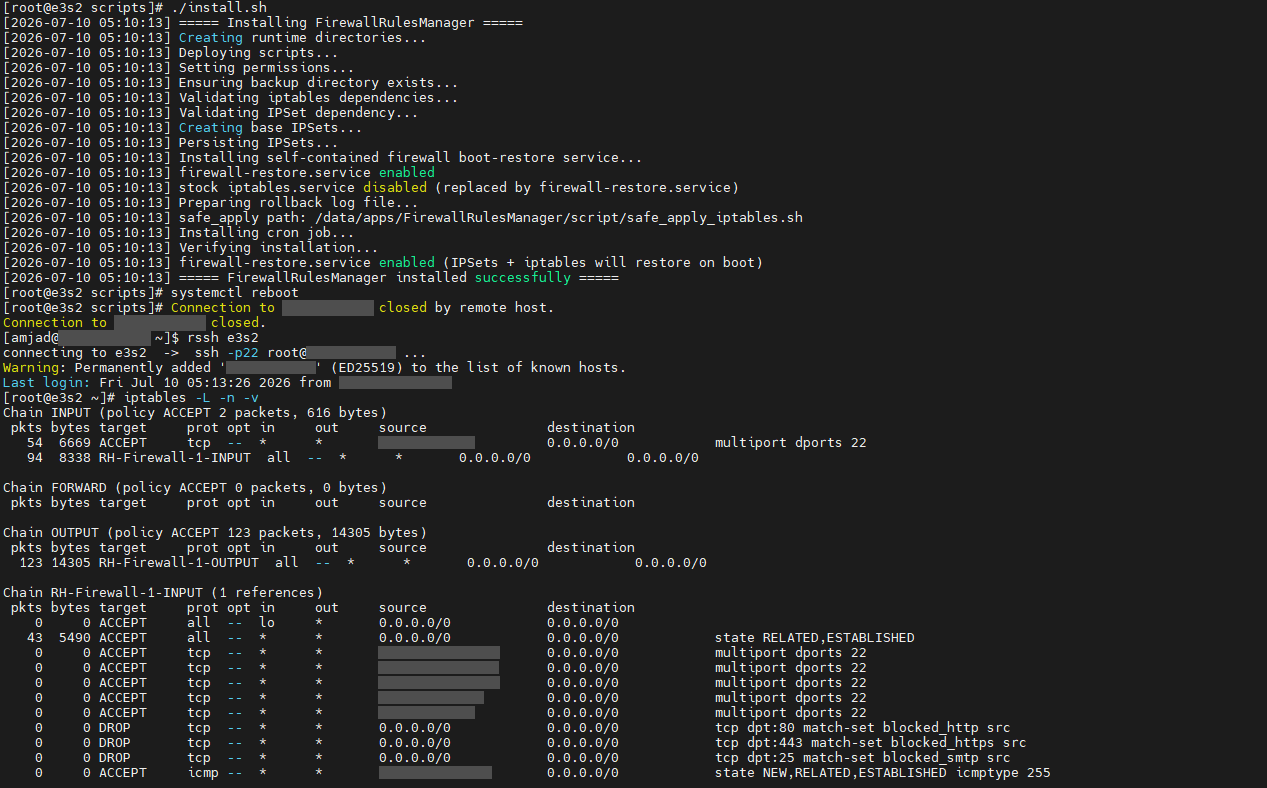
DROP rules that match against IPSets have loaded — which they could not have done if the sets were missing. (This run used an interim unit name, later folded into the standard iptables.service. Addresses redacted.)It is the same failure as every other one on this site: configured, reported healthy, and doing nothing. The service status said enabled. Only the live chain told the truth.
Design decisions
A generator, not a configuration manager. Ansible handles provisioning and onboarding; the ruleset itself is compiled from the database. That means a host’s firewall is reproducible from source at any point in time, and two hosts in the same role are provably identical.
Versioned output. Every generation writes a timestamped artifact alongside the current ruleset. Producing a diff between any two points in time is trivial — which turns “prove your firewall rules are reviewed periodically” from a paperwork exercise into a command.
Revocation as a status change, not a delete. Disabled rules stay in the database with their history intact. The audit trail survives the revocation.
Protected access outside the generated policy. The one rule that guarantees administrative reachability lives in the parent chain, above the jump into generated policy, and is stateless. A bad ruleset, a bad blocklist entry, or connection-tracking exhaustion cannot lock the fleet out.
Certificates drive port 443. Port 443 is opened on a server when its first certificate is issued and closed only when its last one is gone — driven by the certificate lifecycle, not by hand. That bridge is described with the SSL certificate automation it serves.
What I would do differently at scale
Verification, not just application. The system detects intent, generates the fix, and applies it — but does not independently prove the result. Runtime drift detection comparing live state against the generated artifact, plus post-apply assertions that expected rules exist and are matching traffic, would close the loop from configuration management to control assurance.
Egress filtering. The design is inbound-only, which is the common case and the common gap. Outbound policy is where command-and-control traffic and data exfiltration get caught, and it assumes a host will eventually be lost.
Alert when the firewall is absent. The screenshot above was taken six days after that reboot. A check that counts the rules actually loaded in the kernel — and pages someone when the count drops to zero — would have caught it the same morning. Monitoring the service unit would not have; it said enabled throughout.
Threat-intelligence feeds. Blocklists populated manually could be driven from abuse feeds and from the fleet’s own brute-force detections.