Lab build on a single t3.xlarge in a personal AWS account — provisioned by Terraform, measured, and destroyed on 10 October 2026. Every figure on this page comes from the runs in the screenshots. The ArgoCD admin password and commit author details are redacted; the addresses shown are private, inside a VPC that no longer exists.
At a glance
| Stack | k3s v1.36.4 · Istio 1.31.1 · ArgoCD v3.5.3 · kube-prometheus-stack 65.1.1 · Loki · HashiCorp Vault · External Secrets 2.11.0 · Terraform |
| Shape | Two repositories — application source and declared cluster state, deliberately separated |
| Infrastructure | One t3.xlarge, provisioned by Terraform, destroyed the same day |
| Measured | Self-heal in 4 seconds · canary split 171 / 29 against a configured 90 / 10 · full stack at 3.9 GiB |
| Total cost | About $6 |
What it is
A platform where deploying is automatic and releasing is a human decision — and where neither can happen outside git.
CI builds a container image, tags it with the commit SHA, and writes that tag into a second repository. ArgoCD watches that second repository and nothing else. After bootstrap there is exactly one kubectl apply in the entire project — the root Application — and everything after it arrives through a commit.
The constraint worth stating precisely is what CI holds. It has no kubeconfig and no cluster credentials, so a compromised application pipeline has nothing to steal that talks to the cluster directly. Its only route in is a commit to the GitOps repository — attributed, reviewable and revertable, which is the security argument for splitting the repositories.
That is not the same as cannot change the cluster. The token CI uses to write the image tag is a fine-grained one with write access to the GitOps repository alone — and ArgoCD applies whatever lands there. Closing that last gap means CI opening a pull request instead of pushing, or a repository rule limiting the bot to the two values files it actually edits. The separation moves the attack from a stolen kubeconfig to a visible commit; it does not remove it.
Architecture
Helm and Kustomize — not two tools doing one job
Helm packages and templates; Kustomize expresses environment differences. overlays/prod renders the same chart three times — api-v1, api-v2, web — then patches replica counts and topology spread on top. dev renders it twice, smaller, with no canary.
The chart deliberately does not template a Service
The Service spans every version. That is what lets Istio split traffic between v1 and v2 behind one stable DNS name. If each version’s release owned a Service, two releases would fight over the same object — so Services live in base/ as plain manifests.
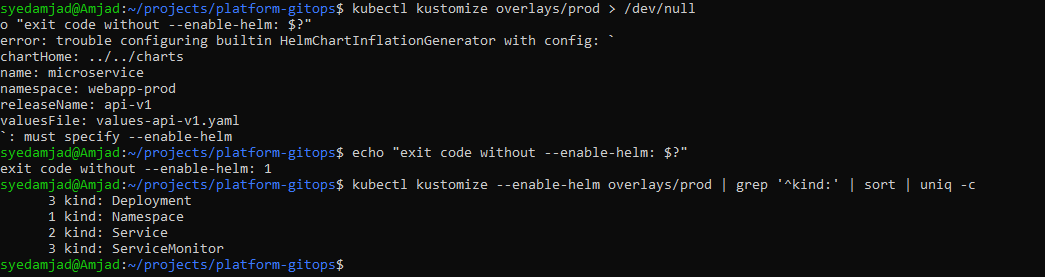
--enable-helm, kustomize v5.7.1 refuses the Helm generator and exits 1. With it, nine resources render. Older kustomize versions fail silently here instead — which is why this one flag comes up again below.Infrastructure as code
The archive this project grew from had no provisioning at all — the bootstrap script simply assumed a machine existed. That gap is filled by a small Terraform stack: one EC2 instance, one security group, one key pair, a subnet, an internet gateway and its routing. Nine resources.
| Decision | Reason |
|---|---|
Port 22 only, from a /32 | Every UI — ArgoCD, Grafana, Prometheus, Alertmanager, Kiali — is reached through an SSH tunnel. Nothing else is exposed. |
An existing SSH key, not tls_private_key | That resource writes the private key into terraform.tfstate in plaintext. State is the one file in an IaC repo you cannot afford to leak. |
| IMDSv2 required | The v1 metadata endpoint is reachable from inside any pod, which turns an SSRF into a credential read. Free to enforce. |
| No Elastic IP | An EIP bills while unattached — precisely when you have forgotten it exists. |
ignore_changes = [ami] | The AMI resolves to “most recent”, so an Ubuntu republish would otherwise render as a plan that destroys a day-old cluster. |
The teardown script verifies against AWS, not against Terraform, and exits non-zero if anything survives. Those are two different claims, and only the second one matters when the bill arrives. That distinction was not academic: one terraform destroy silently failed to run and left the instance billing for 24 hours before the check caught it.
What the platform does, measured
Self-heal
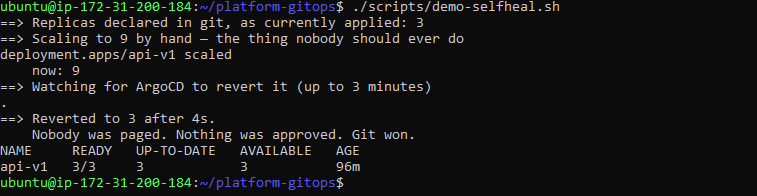
A deployment scaled to 9 replicas by hand is back to the git-declared 3 four seconds later.
Progressive delivery, counted rather than asserted
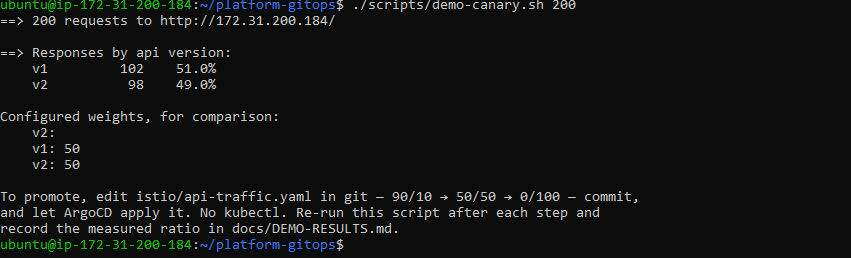
Asserting that a 90/10 split was configured proves nothing. Counting 171 responses against 29 proves the mesh is actually routing. Both rows below were measured through the ingress gateway, counted from the version each response reported — not read back from the VirtualService.
| Weights in git | Requests | v1 measured | v2 measured | Deviation |
|---|---|---|---|---|
| 90 / 10 | 200 | 171 (85.5%) | 29 (14.5%) | −4.5 pp |
| 50 / 50 | 200 | 102 (51.0%) | 98 (49.0%) | +1.0 pp |
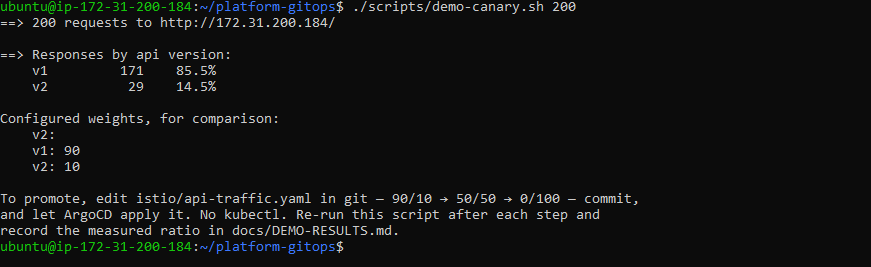
The deviation is correct behaviour, not a misconfiguration. Istio’s distribution is probabilistic per request, not a strict round robin, and the smaller arm deviates more at n=200 — exactly as it should. Reported rather than rounded away.
One tidier number was deliberately thrown out. A cumulative http_requests_total ratio read 91.8 / 8.2 at one point — a neat-looking confirmation of 90/10. Those counters included traffic sent by kubectl exec straight to the pods, which bypasses the VirtualService entirely. A plausible number measuring the wrong thing is worse than no number.
Changing the weights is a git commit, not a kubectl command:
edit istio/api-traffic.yaml → commit → push → ArgoCD applies → re-measure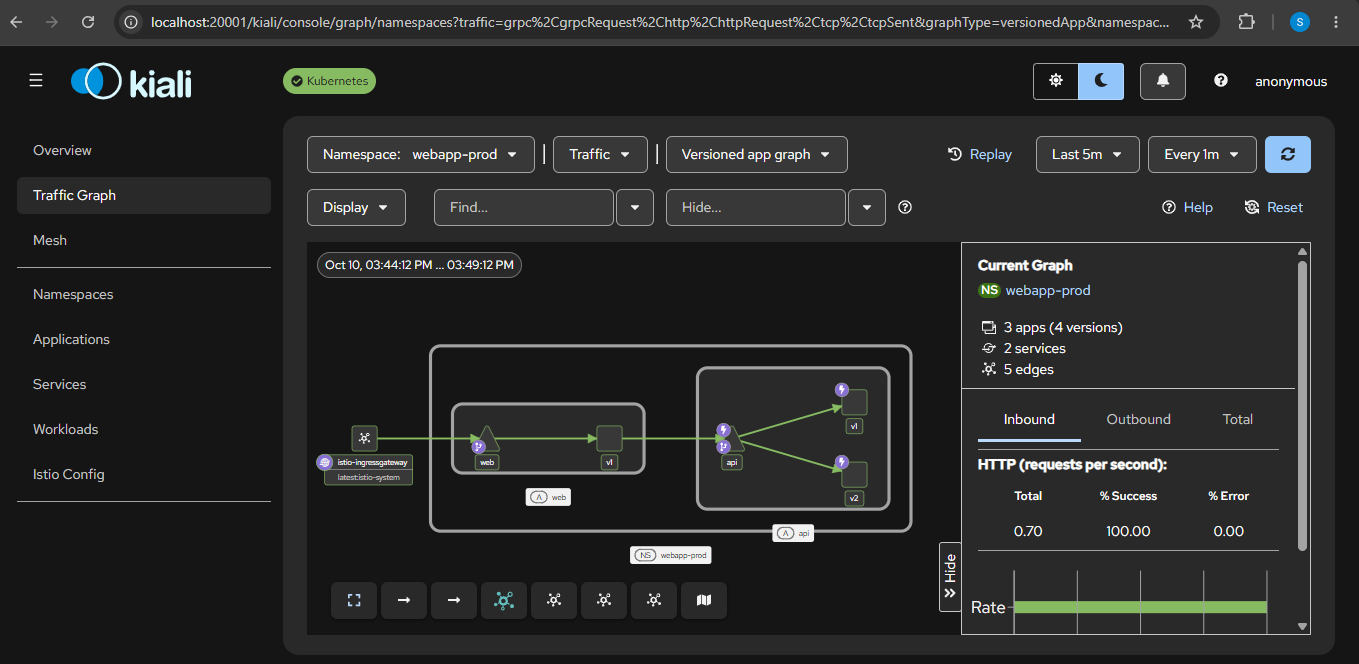
istio-ingressgateway → web → api → {v1, v2} — two hops, four versions, five edges, 100% success. The second hop is what makes this a service graph rather than a single box — and, as it turned out, what broke header routing.Metrics and logs, correlated
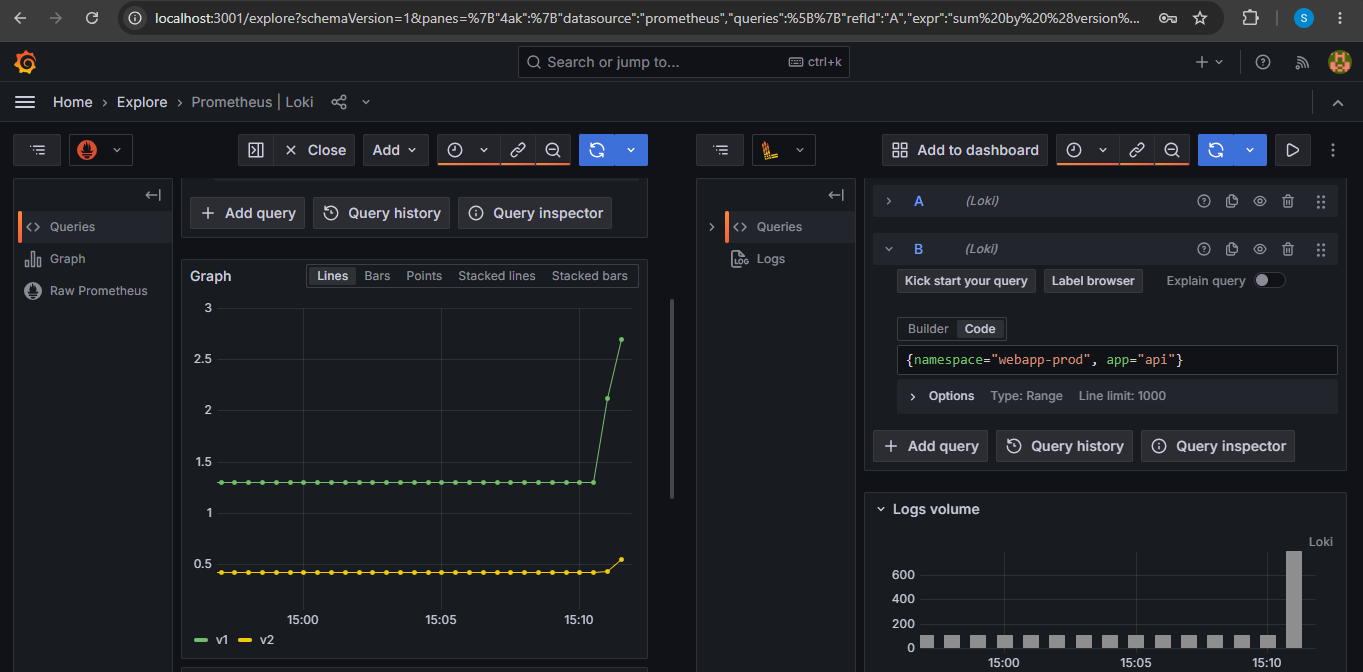
version label is what makes the canary countable — a blended error rate would hide a bad canary behind a good stable.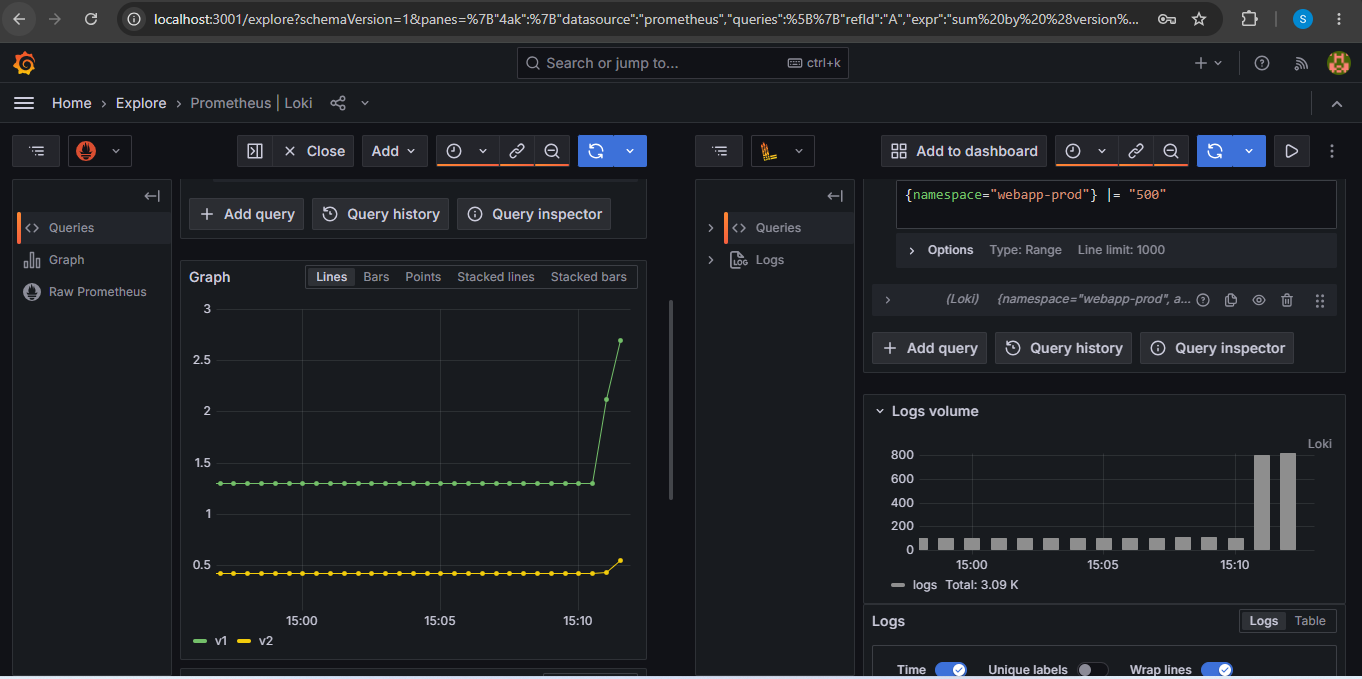
{namespace="webapp-prod"} |= "500".Alerting that has actually fired
The application exposes /boom and /slow for exactly one reason: an alert you have never seen fire is a configuration, not an alert. Driving errors through /boom pushed the error-budget rule past its for: 10m window and fired WebappErrorBudgetBurn at severity critical.
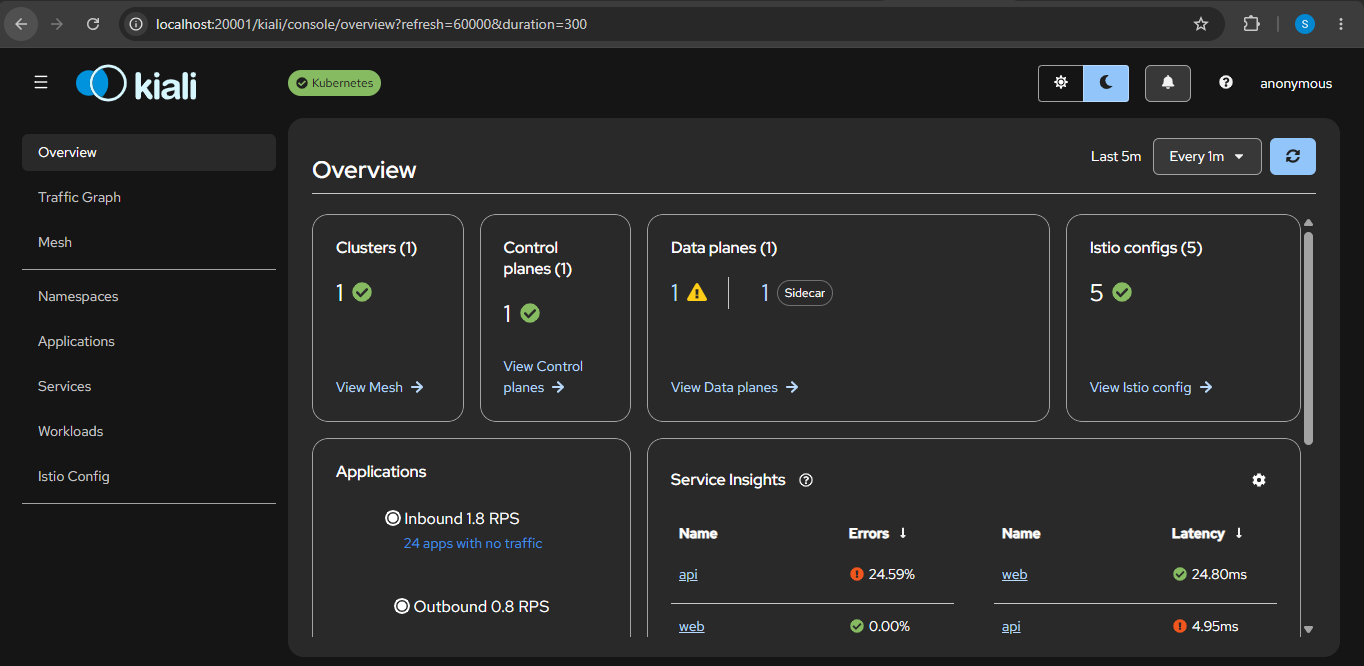
api, 0.00% on web — only api has the failure endpoint.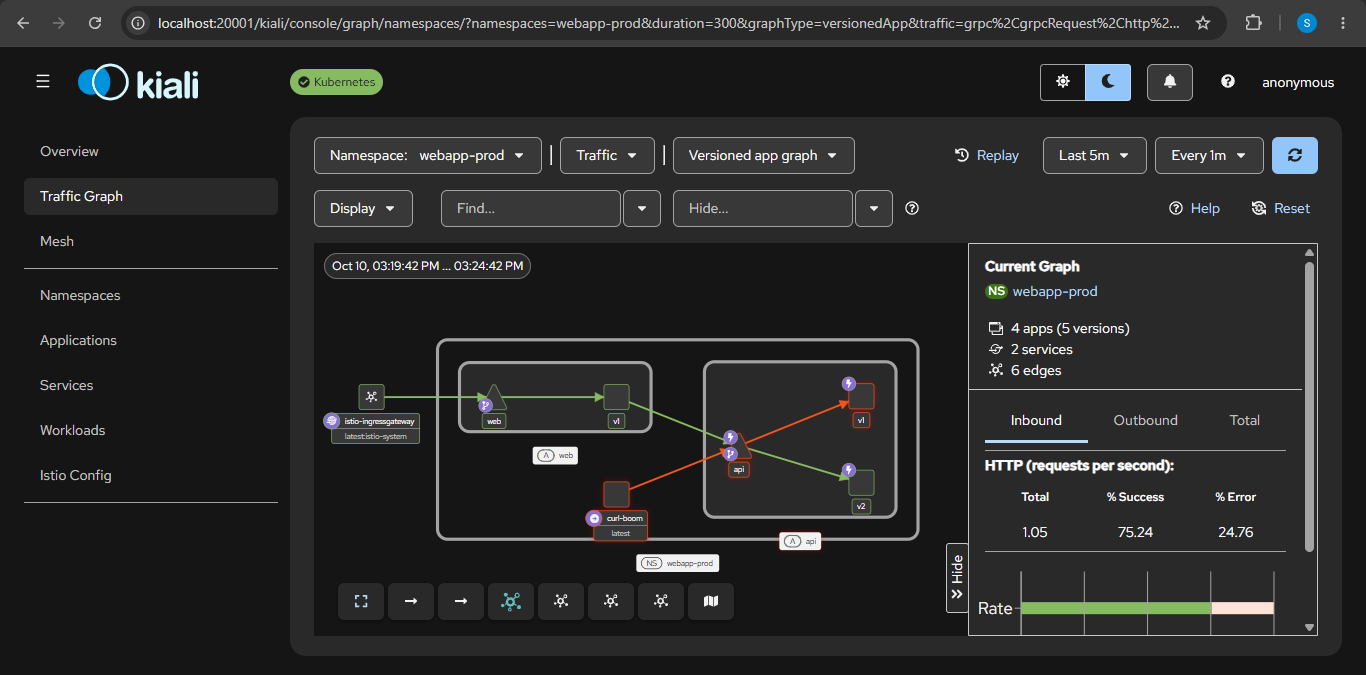
curl-boom test pod driving /boom straight at api — the normal path through the gateway stays green.Secrets that are never in git
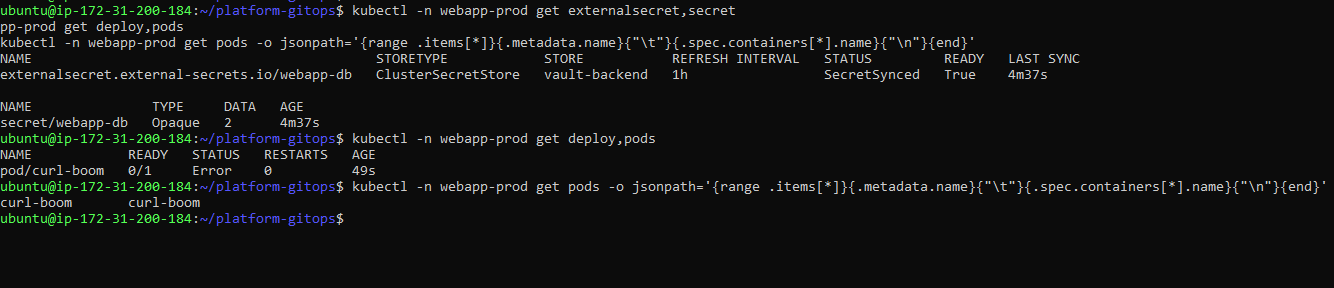
SecretSynced, and the Secret in place before any Deployment exists in the namespace — the order the sync waves are there to give. (The one pod listed is a leftover curl test pod.)The repository contains the reference; External Secrets fetches the value from Vault at runtime. Rotating a credential in Vault propagated to the cluster with no commit, no pipeline run and no redeployment — with one caveat, under Honest limitations.
What went wrong
This is the part worth reading. Seventeen defects surfaced during the build, between a local dry run on 23 September and the final session on 10 October. Each is recorded in the repository with its symptom, the misleading error it produced, and the reasoning — not just the fix. The most instructive:
A route that silently discarded every packet
The AWS account’s default VPC had been stripped at some point: all six default subnets deleted, the internet gateway deleted, and the main route table still carrying 0.0.0.0/0 to the dead gateway in state blackhole.
A blackhole route is not an error. Had the stack inherited that route table, terraform apply would have succeeded and the instance would have booted and passed its status checks — and SSH would have timed out. With no gateway there is nothing for inbound traffic to enter through, and the replies follow the default route into the blackhole anyway. An SSH timeout sends you to the security group and your own /32; the route table of a default VPC is the last place anyone looks. (The full story.)
The Terraform now declares its own gateway, subnet and route table rather than inheriting account state nobody is maintaining.
set -e turning a cosmetic error into a silent omission
ArgoCD’s ApplicationSet CRD is larger than Kubernetes’ 262144-byte limit on the annotation that client-side apply writes, so kubectl apply refused it. That on its own is harmless — ArgoCD runs fine without ApplicationSet.
But under set -euo pipefail the failure aborted the install script before a line further down the same file:
kubectl -n argocd patch configmap argocd-cm --type merge \
  -p '{"data":{"kustomize.buildOptions":"--enable-helm"}}'
That is the flag without which none of the Helm-based overlays render. With an older kustomize it is the project’s signature failure — ArgoCD reports a successful sync having deployed nothing but the Services. An oversized annotation on an unrelated CRD would have surfaced an hour later as that, with nothing connecting the two. The fix is server-side apply, which tracks ownership in managedFields and has no such limit. (The full story.)
One allowlist entry short, four applications broken
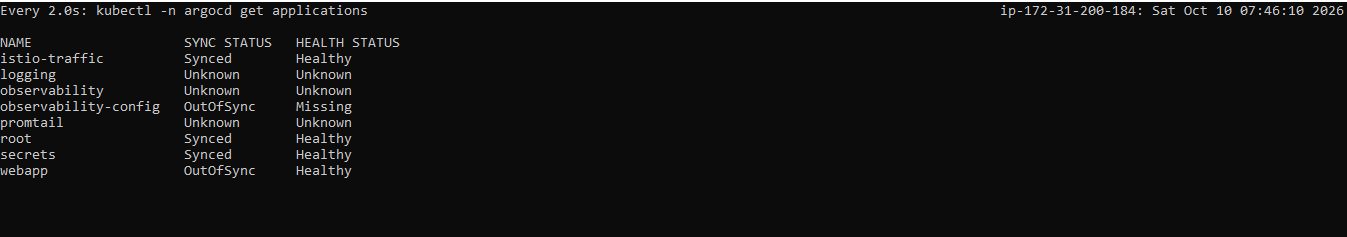
Unknown, one Missing — while istio-traffic, the last wave, reports Synced and Healthy. That second detail is its own finding: the waves did not hold.The ArgoCD AppProject permitted only the GitOps repository as a source. Three Applications pull Helm charts from upstream; they were refused — and because kube-prometheus-stack never installed, two further Applications failed with failed to discover server resources for group version monitoring.coreos.com/v1.
Only one of the four errors named the real cause. Debugging from the last error would have led into chart internals and found nothing.
It also exposed a genuine design tension. The original project denied ClusterRole and ClusterRoleBinding, on the reasoning that privilege escalation through a committed manifest is the GitOps-specific attack. That reasoning is correct — and incompatible with installing a monitoring operator that legitimately needs cluster RBAC. There is no clever resolution: a platform that installs an operator through GitOps is a platform whose repository can create cluster RBAC. The project widened the allowlist and says so in the file, rather than keeping a comment describing a control no longer there. (It is also why the CI token above matters more than it first appears.) (The full story.)
Security and observability in direct conflict
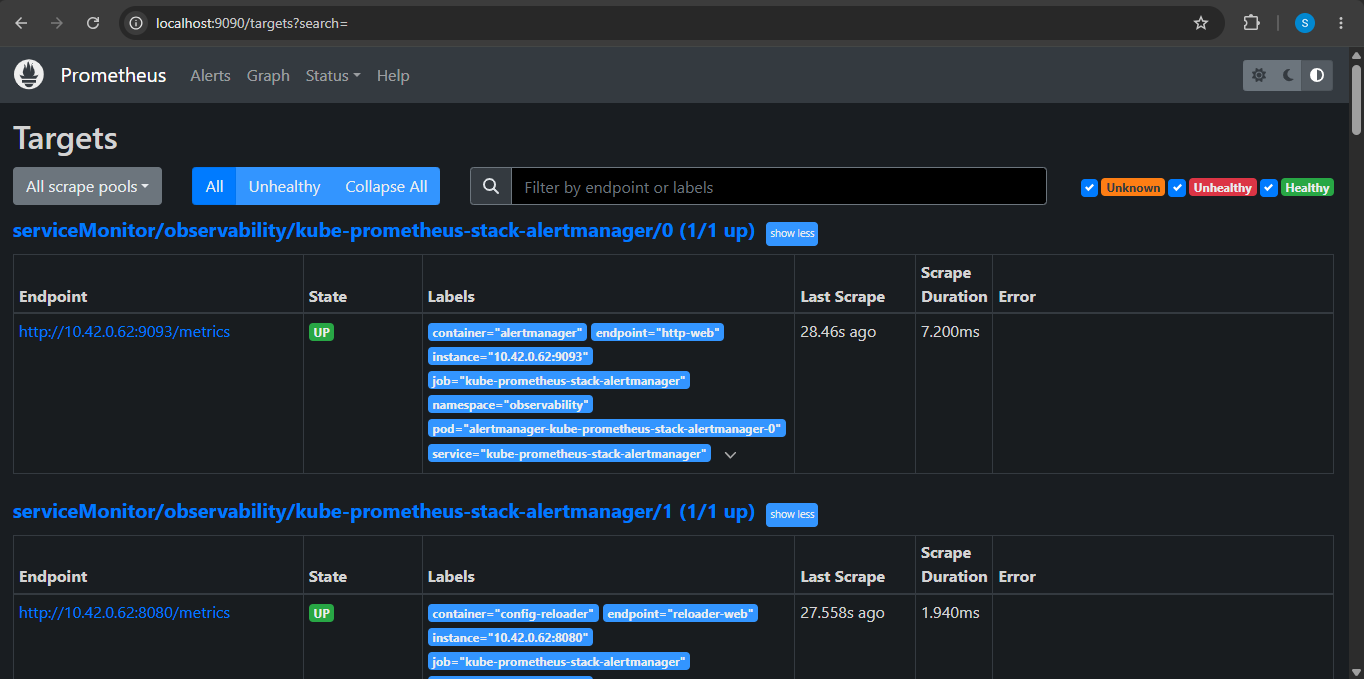
STRICT mutual TLS across the application namespace meant the Istio sidecar reset every Prometheus scrape. Targets sat permanently DOWN with connection reset by peer, while /metrics answered 200 from inside the pod. Nothing was broken — the mesh was enforcing precisely what it had been told to.
The quick fix is to relax mTLS to PERMISSIVE. It works in one line and quietly discards the control, because the application port carries real traffic as well as metrics.
It took four attempts to do it properly:
- Scrape the app port — targets appeared and failed. Right diagnosis, wrong layer.
ServiceMonitorwithtargetPort: 15020— targets vanished entirely. A ServiceMonitor discovers through the Service’s endpoints, so it can only select a port the Service exposes.PodMonitorwithtargetPort: 15020— also zero targets. Both forms compile down to a relabel that keeps only declared container ports, and 15020 listens without being declared.- Publish 15020 as a Service port, then attach a ServiceMonitor to it — works. A Service forwards to any pod port, declared or not, which is the one property neither monitor CRD has.
Attempt 2 is the one worth remembering: it made the symptom worse while being a step closer. A failing target tells you something is wrong; a missing target looks like nothing was ever created.
STRICT mTLS was kept. Istio’s merged telemetry port carries the application’s own metrics alongside Envoy’s, and Istio exempts that port from mTLS precisely so monitoring survives. The cleaner production answer is a third thing neither option does — serve /metrics on its own port — and that is an application change, noted as the follow-up.
And the fix created a fault two files away. Publishing 15020 made the Service multi-port, and a VirtualService destination pointing at a multi-port Service no longer identifies a port. Nothing failed: routing continued, ArgoCD stayed Synced and Healthy, every pod stayed Running. Only istioctl analyze saw it — IST0112 — and a Kiali badge easily mistaken for the demo’s deliberate errors. Pinning port.number: 8000 on the three destinations cleared it. (The full story.)
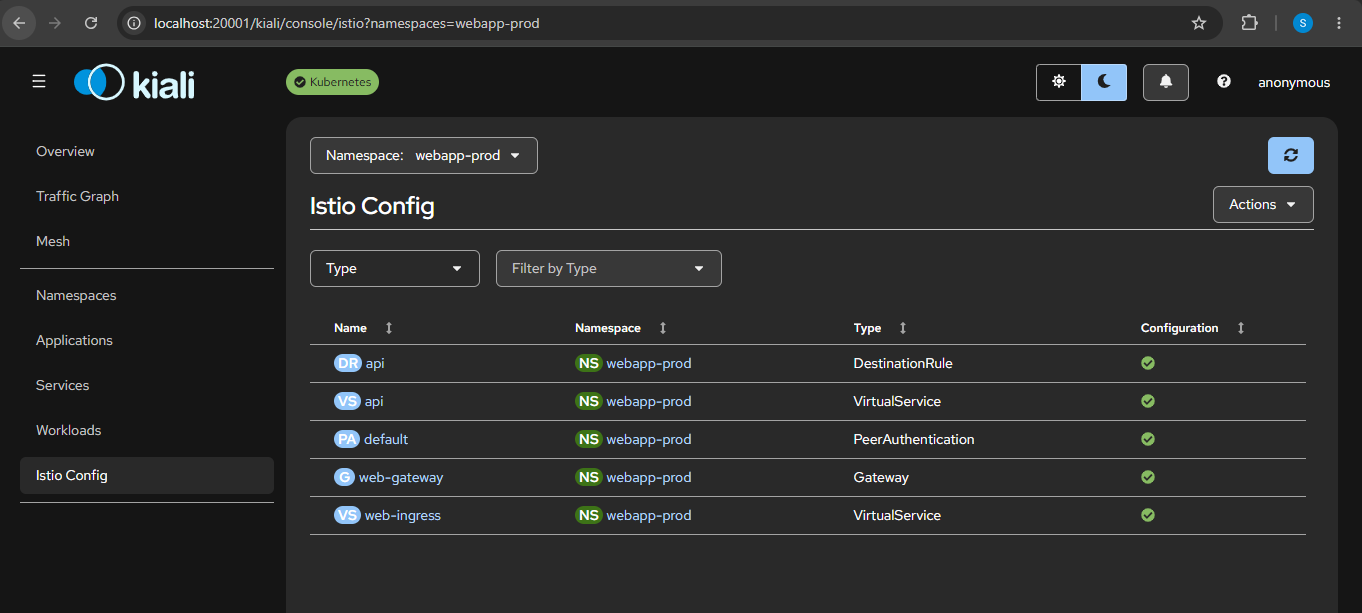
PeerAuthentication that was kept rather than relaxed.And one left open
Header-based canary routing — x-canary: true should pin a request to v2 — does not work, and the repository says so.
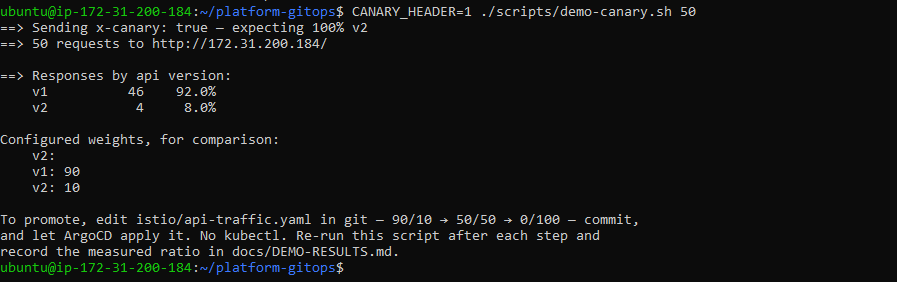
Expected 0 v1 / 50 v2. Got 46/4 at 90/10 weights, and 27/23 at 50/50. The result tracks the weights, which is the proof: if the header rule were matching, the weights would be irrelevant.
The mesh configuration is correct. The web service simply never forwards the inbound header on its outbound call to api, so the header dies at the first hop, and api’s rule evaluates against a request that no longer carries it.
Header-based routing is often described as free with Istio. It is free for single-hop paths. On a two-hop path it is an application contract — the same requirement distributed tracing has, for the same reason. A mesh can route on context it can see, but only the application can carry that context across a call it originates.
Left open rather than patched, because fixing it properly means an application change, a CI run and a redeploy — which is exactly the deploy-versus-release distinction the rest of the project is about. (The full story.)
Honest limitations
These are in the repository too, and they stay there.
- Vault runs in dev mode — unsealed, in-memory, root token, and it loses everything when the pod restarts. That is correct for demonstrating the External Secrets pattern and wrong for anything else. It bit during the build: a restart wiped the seeded secrets, and they had to be re-seeded.
- Rotation updates the Secret, not the running process.
envFromis read at container start, so pods keep the old value until restarted. Making that automatic needs a file mount with a watcher, or Reloader. Claiming zero-restart rotation would be overclaiming. - Alertmanager posts to a webhook, not a real destination. An alert that fires into nothing is the same class of problem as everything else here.
- Sync waves did not fully hold. Wave 4 reached Healthy while waves 1 and 2 were failing validation, because an Application rejected at validation sits in
Unknown, which does not block the wayProgressingdoes. The ordering guarantee is weaker than the documentation implies. - CI’s token can write to the GitOps repository, and ArgoCD applies what it finds there. The repository split removes cluster credentials from CI; it does not make a pipeline compromise harmless. A pull-request gate or a path-restricted rule for the bot is the missing piece.
- Two demonstrations were not run — pruning a removed resource, and the final 0/100 promotion. The session ended first, and they are recorded as not run rather than left out.
- The sizing estimate was wrong, in the safe direction. The design argued for 16 GB on the basis of a ~7.4 GiB footprint. The measured figure was 3.9 GiB; an 8 GB node would have fitted. The larger instance still stands for the follow-on project, but the original number was a guess carrying more confidence than it had earned.
- Zabbix earns its place only where non-Kubernetes infrastructure exists. The repository keeps a values file and a note on when it is warranted; in a greenfield Kubernetes estate you would not add it. Saying that is a more useful answer than deploying it and implying it was necessary.
Cost discipline
A t3.xlarge bills about $0.166 an hour — roughly $120 a month if left running. The whole build came to about $6, because the environment is created and destroyed per session:
./scripts/lab-up.sh     # terraform apply, wait for SSH
./scripts/lab-down.sh   # terraform destroy, then verify against AWS
The teardown script checks for instances, orphaned EBS volumes and — the one people forget — unattached Elastic IPs, which bill precisely when nobody remembers they exist. It exits non-zero if anything survives.
Rebuilding is about an hour, entirely from git. Nothing in the cluster is precious, and being able to destroy it on a whim is the argument for the whole architecture rather than a cost-saving afterthought.
The build, start to finish
Expand the full walkthrough — bootstrap to running platform
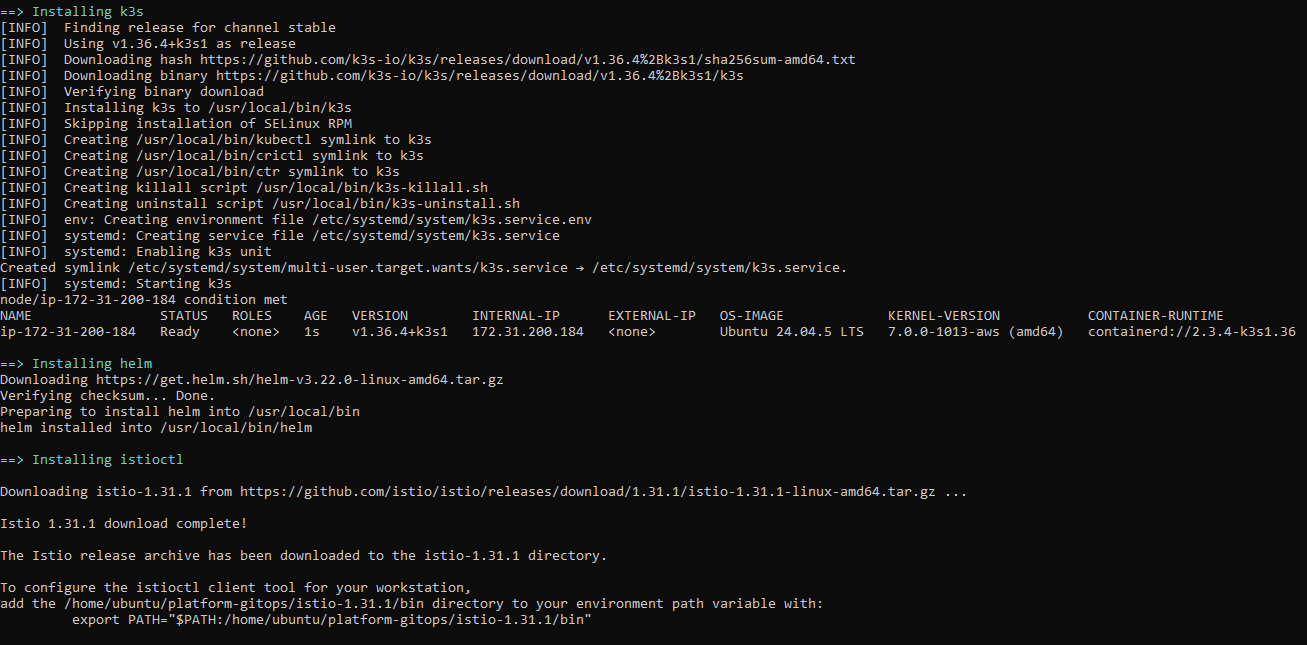
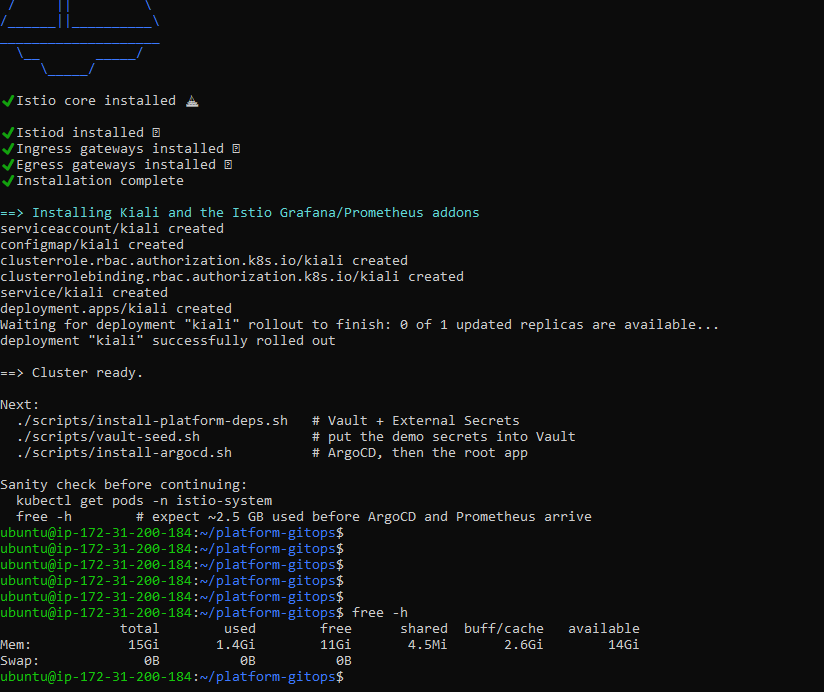
1 · A fresh node becomes a cluster
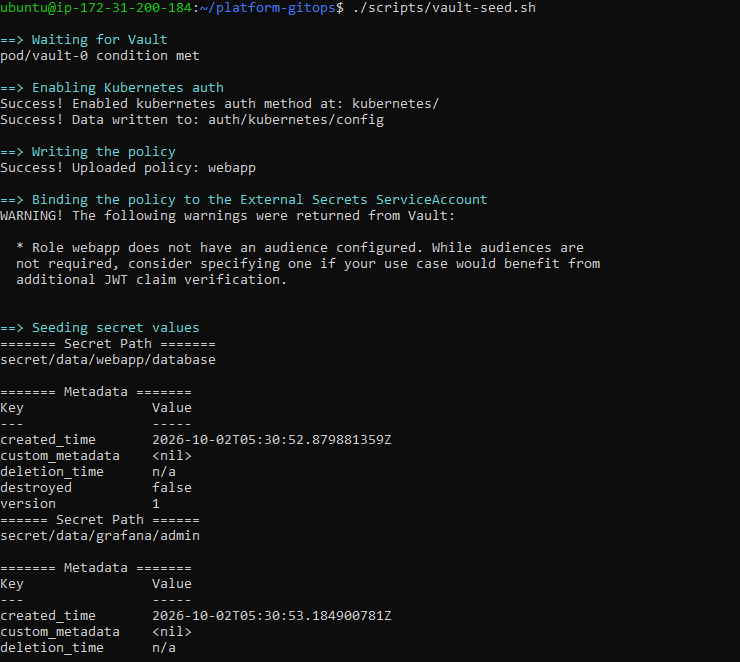
2 · Secrets before anything that needs them
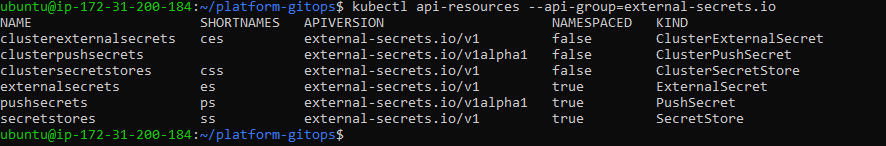
v1 only. Manifests written against v1beta1 fail with no matches for kind, which reads like a typo in a file that is actually correct for the version it was written against.3 · ArgoCD, and the flag everything depends on
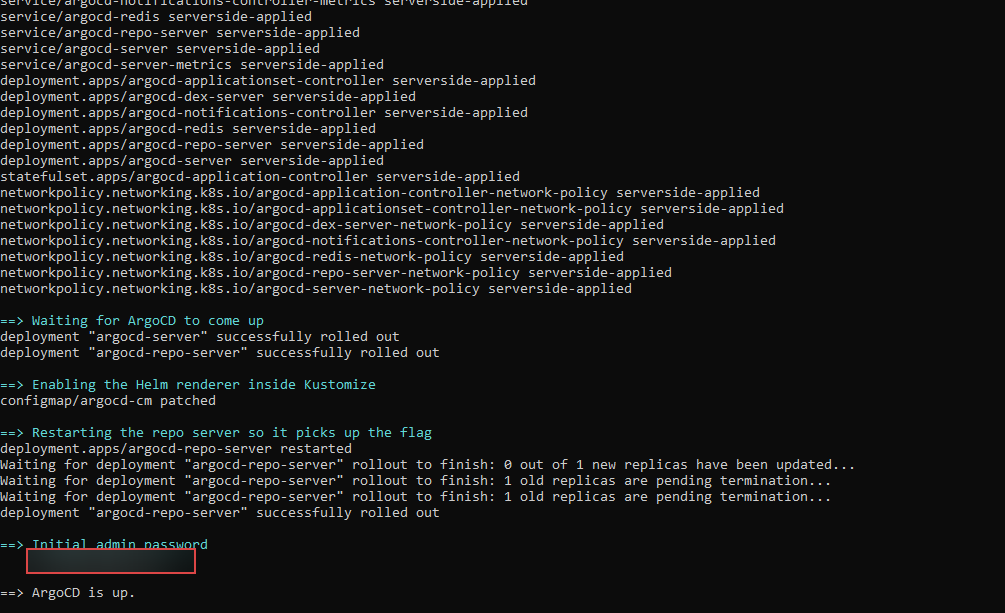
--enable-helm patch lands at the end, and the whole platform depends on it. (Admin password redacted.)4 · Handing the cluster to git
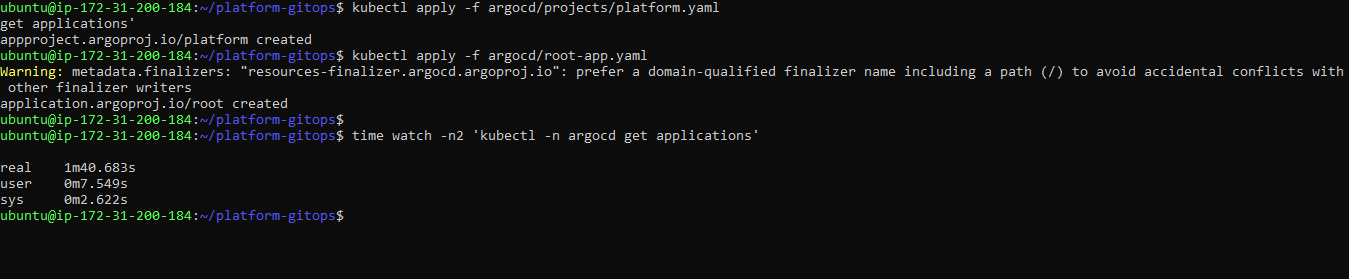
watch ran, not a time-to-healthy: the first attempt failed on the allowlist defects, so a clean empty-to-Healthy figure was never measured — and is not claimed.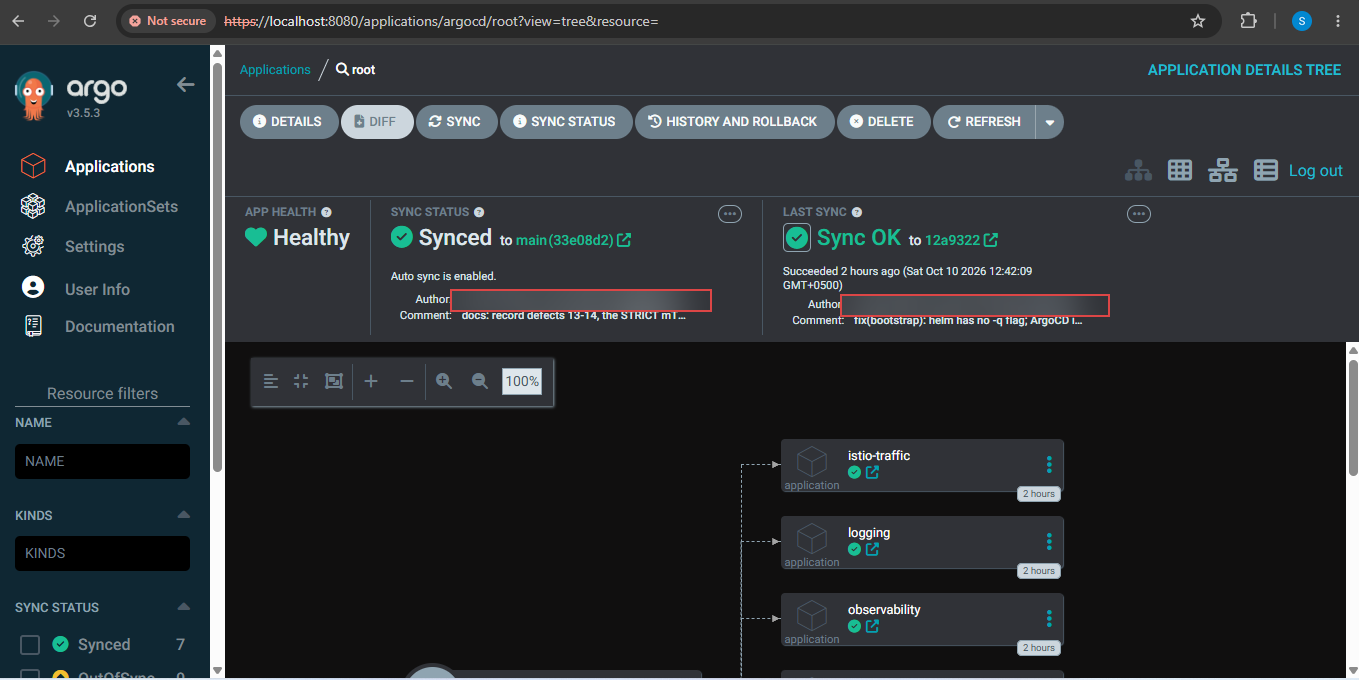
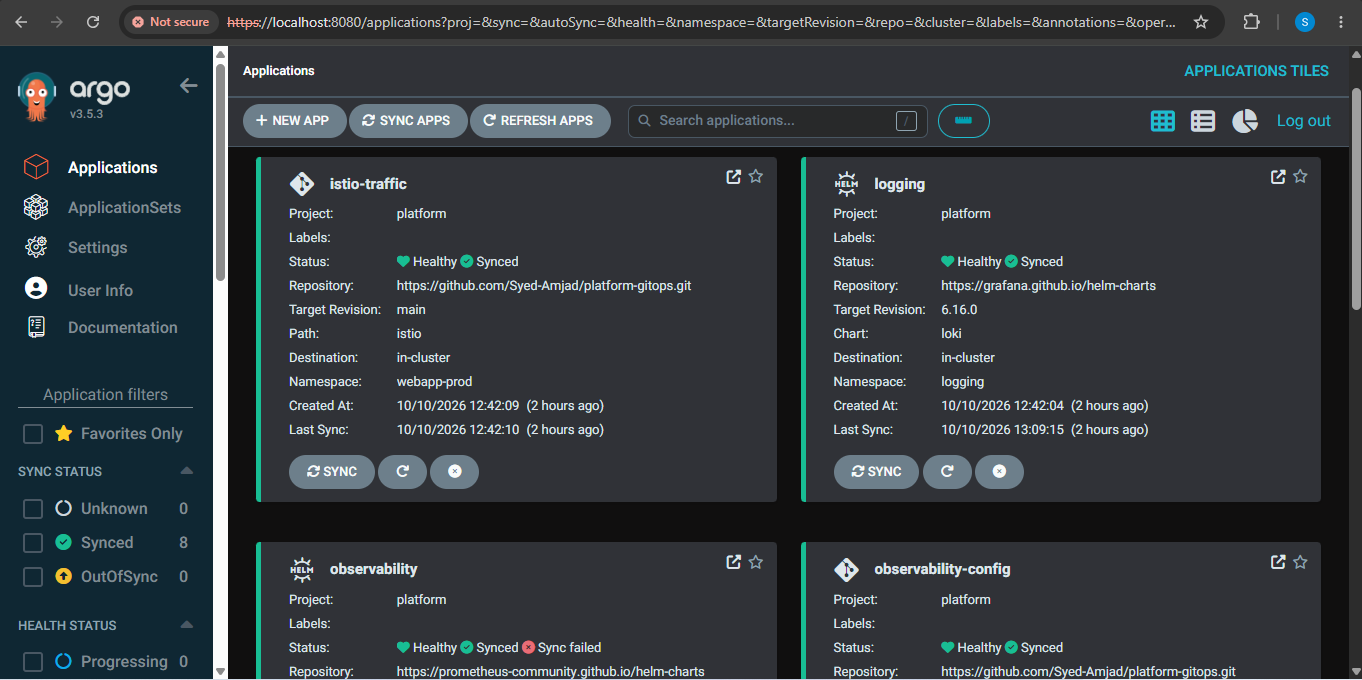
observability is the result of an earlier sync operation — ArgoCD reports the current state and the last operation separately.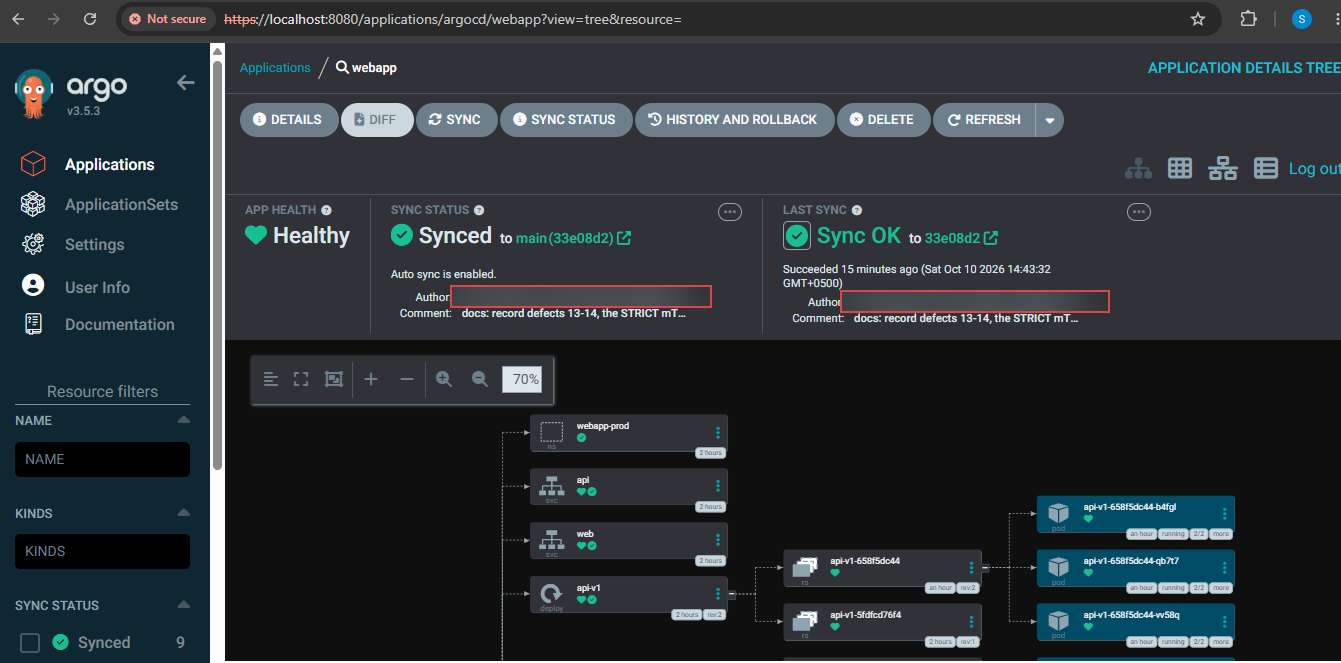
2/2 is the app plus its Istio sidecar.5 · Observability wired up
Repositories
| platform-gitops | Declared cluster state, Terraform, the demonstration scripts, and docs/DEMO-RESULTS.md — every defect with its reasoning |
| k8s-platform-app | Two FastAPI services, non-root on numeric UID 10001 with a read-only root filesystem, and the CI that publishes them |
Both images run non-root on a numeric UID rather than a username — runAsNonRoot cannot verify a name at admission time, so an image whose USER is a name gets rejected by the policy layer that comes next.
What comes next
The same delivery pattern, rebuilt from git, gained a Zero-Trust supply-chain layer: Kyverno admission policy, Falco runtime detection, Trivy scanning and signed images — each attacked on purpose. This project builds the delivery path; that one makes it prove every artifact it deploys.