Lab build on a single t3.large in a personal AWS account, provisioned by Terraform and destroyed between sessions. Every error message quoted on this page is copied from the attack transcripts in the repository. The addresses shown are private, inside a VPC that no longer exists.
At a glance
| Stack | k3s v1.36.5 · Istio 1.26.2 (CNI mode) · Kyverno chart 3.9.1 · Falco chart 9.2.0 · ArgoCD v2.13.2 · cosign v2.4.1 · Terraform |
| Shape | Two repositories — application source and declared cluster state, deliberately separated |
| Verified before attacking | 15 passed, 0 failed, 0 skipped behavioural checks |
| Attacks | 7 run, twice — once in Audit, once in Enforce. 6 held. 1 failed, and is published as a failure |
| Defects | 15 found — 6 in the platform and its dependencies, 9 in my own tooling |
| Total cost | Under $1 — one t3.large for about six hours |
The claim this project had to earn
Most security write-ups show a configuration and assert that it works. This one assumes the opposite until proven: a policy that is accepted by the API server is not a policy that is enforced, and the only way to tell the difference is to attack it and read which component answers.
So the platform was built, and then seven attacks were run against it. Each attack targets one named layer. Each result records the actual error message, because the message is the evidence — it names which control spoke. “Rejected” in a results column could have come from any of four places.
Six of the seven held. One did not, and the reason it did not is the most useful thing on this page.
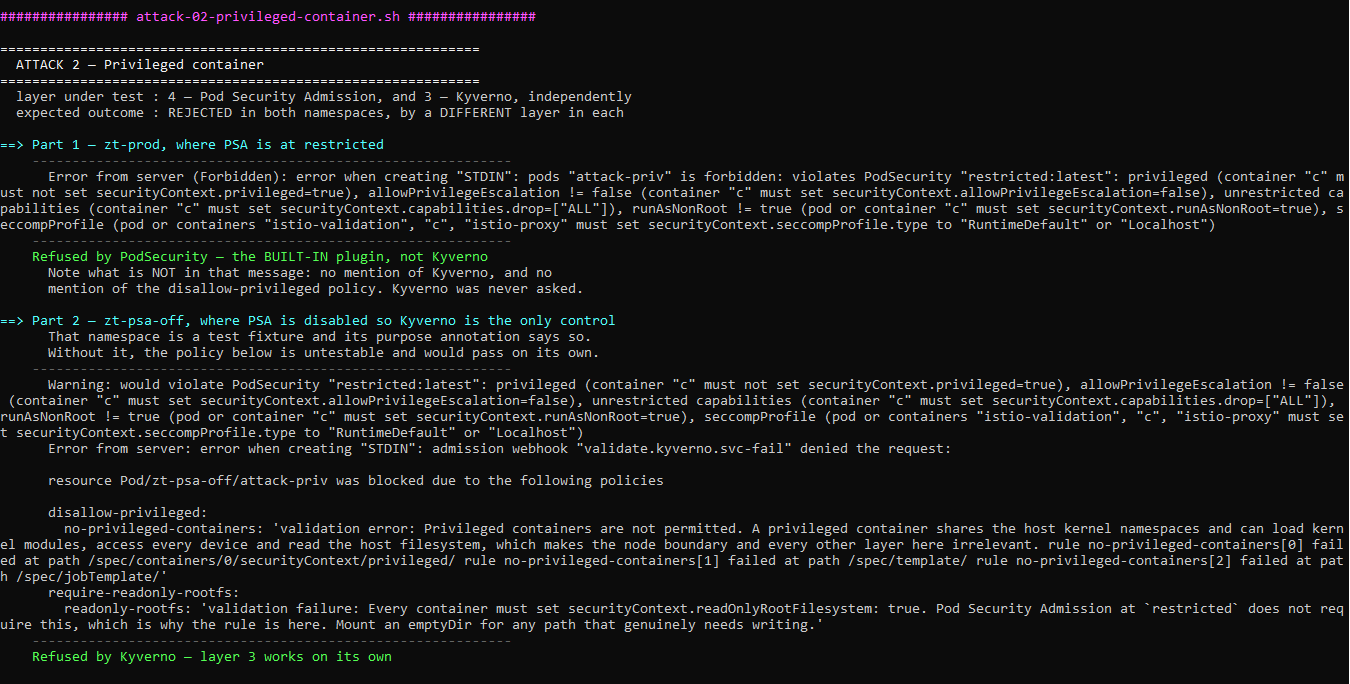
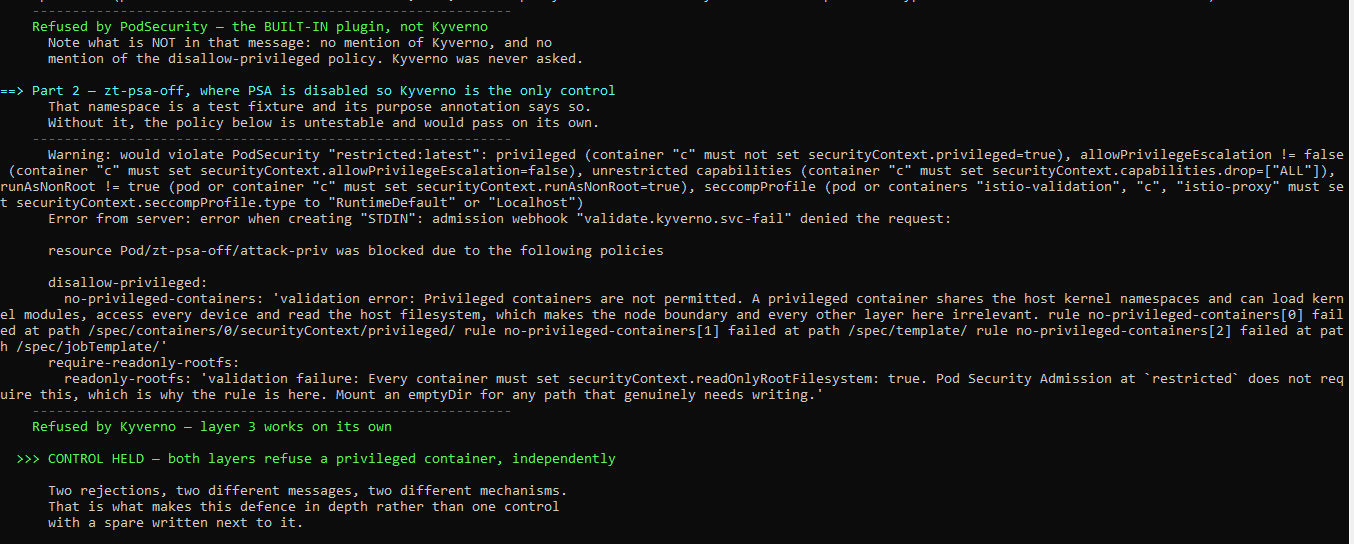
zt-prod by the built-in PodSecurity plugin — no mention of Kyverno, which was never asked — and in zt-psa-off by Kyverno, naming the policy and the exact field path.The second namespace is a test fixture with Pod Security Admission deliberately turned off, and its annotation says so. Without it the Kyverno rule is untestable: in every governed namespace PSA refuses the pod first, so the Kyverno policy would appear to pass while never having been exercised.
Architecture
| Layer | Control | What it stops |
|---|---|---|
| 1 | Build provenance — cosign keyless signing, Fulcio certificate, Rekor transparency log | An image that did not come from this pipeline |
| 2 | GitOps — ArgoCD, automated sync, selfHeal, pruning | The cluster quietly diverging from git |
| 3 | Admission policy — Kyverno: signature, registry, privilege, resources, read-only root | A non-compliant workload being created at all |
| 4 | Pod Security Admission — restricted in every governed namespace | Privileged containers, via the built-in plugin rather than a webhook |
| 5 | NetworkPolicy — default-deny, explicit allows | Lateral movement at L3/L4 |
| 6 | Service mesh — Istio STRICT mTLS, AuthorizationPolicy, REGISTRY_ONLY egress | Unauthenticated callers and undeclared outbound destinations |
| 7 | Runtime detection — Falco with rules scoped to this cluster | What the first six did not prevent |
The design argument is that these are independent, not redundant. Attack 2, above, is the proof.
What was measured
Controls verified before any attack ran
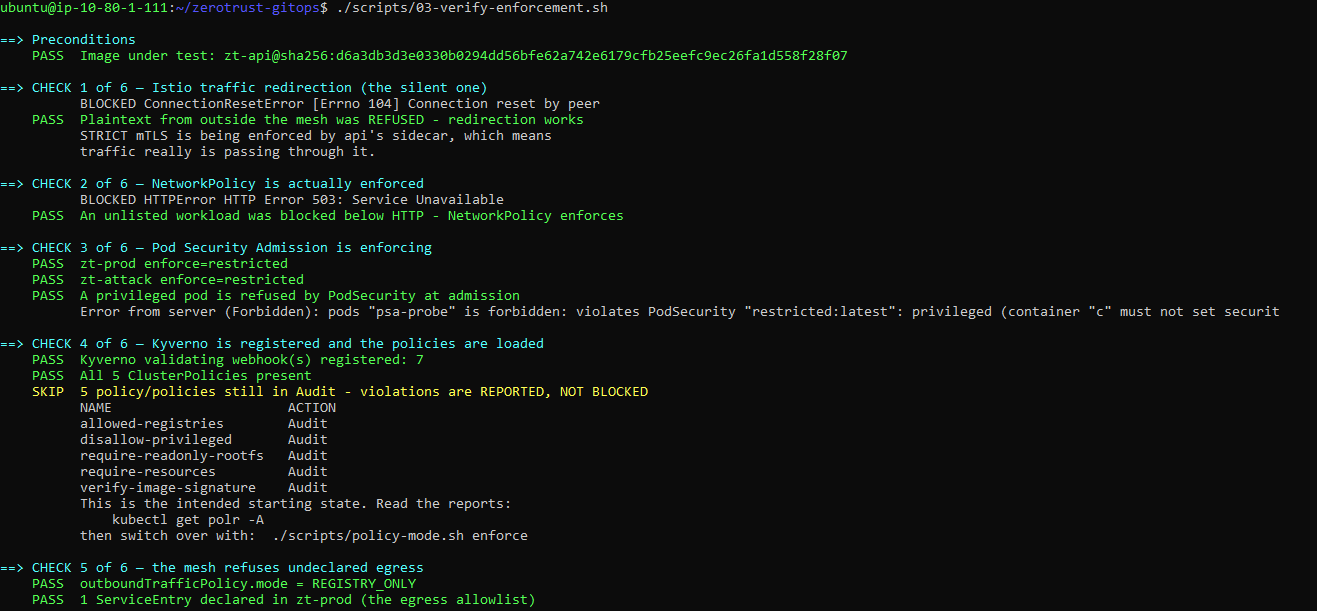
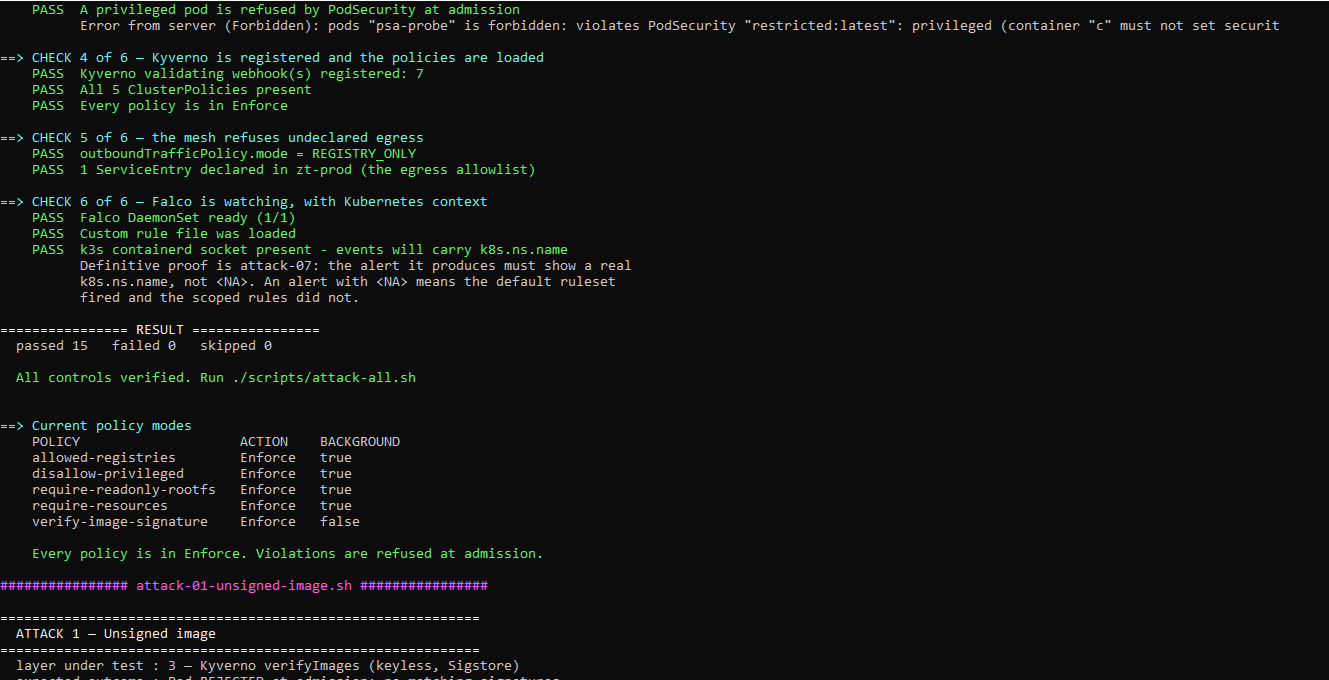
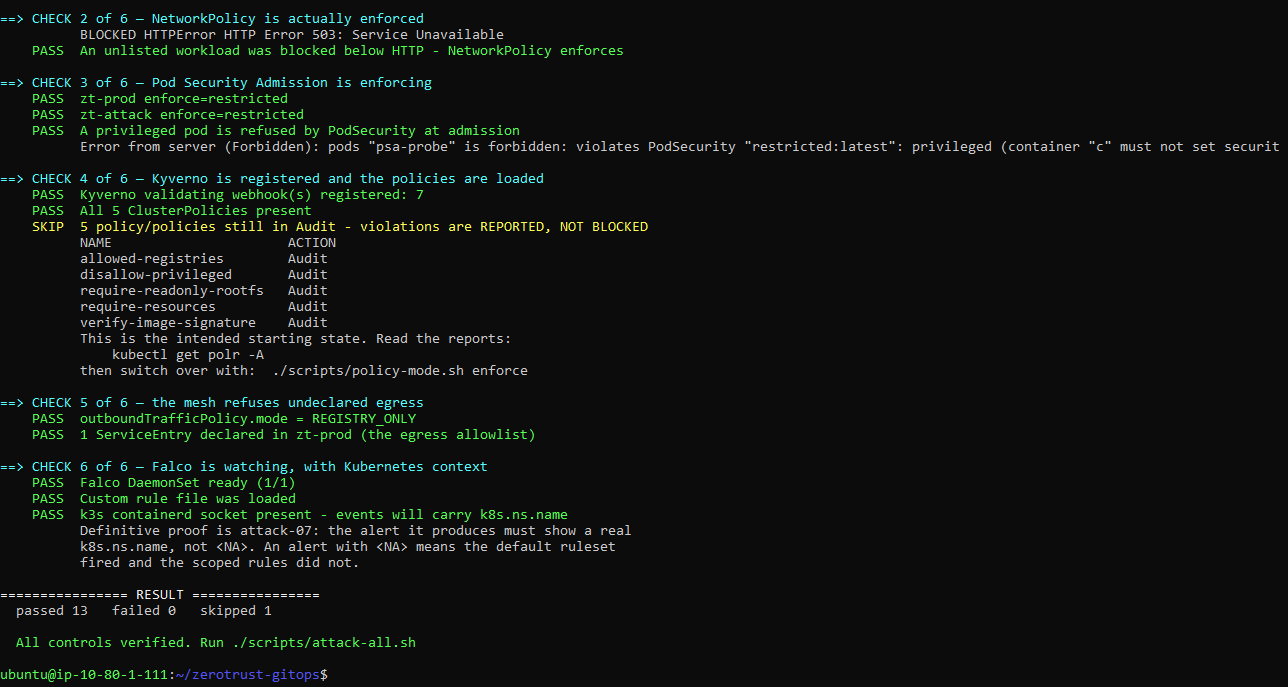
03-verify-enforcement.sh tests behaviour, not YAML. It opens a plaintext connection from outside the mesh, submits a privileged pod, counts the loaded policies, and reads the mesh’s outbound mode.
================ RESULT ================
  passed 15   failed 0   skipped 0
The check that matters most is the first one:
CHECK 1 of 6 — Istio traffic redirection (the silent one)
      BLOCKED ConnectionResetError [Errno 104] Connection reset by peer
  PASS  Plaintext from outside the mesh was REFUSED - redirection works
That connection reset is the only honest proof that traffic is actually passing through the sidecars. Every mesh guarantee is enforced by an Envoy that traffic has to traverse — not by the policy objects, which apply cleanly whether or not anything reads them.
The seven attacks
| # | Attack | Layer | Result | The message that proves it |
|---|---|---|---|---|
| 1 | Unsigned image | 3 | Held | verify-ghcr-signature: 'failed to verify image … .attestors[0].entries[0].keyless: no signatures found' |
| 2 | Privileged container | 4 and 3, separately | Held twice | PSA: violates PodSecurity "restricted:latest": privileged. Kyverno: no-privileged-containers … failed at path /spec/containers/0/securityContext/privileged/ |
| 3 | Image from an undeclared registry | 3 | Held | only-trusted-registries … failed at path /spec/containers/0/image/ |
| 4 | Call from an unauthorised workload | 6 | Held | With a sidecar: HTTP 403 RBAC: access denied. Without: ConnectionResetError [Errno 104] |
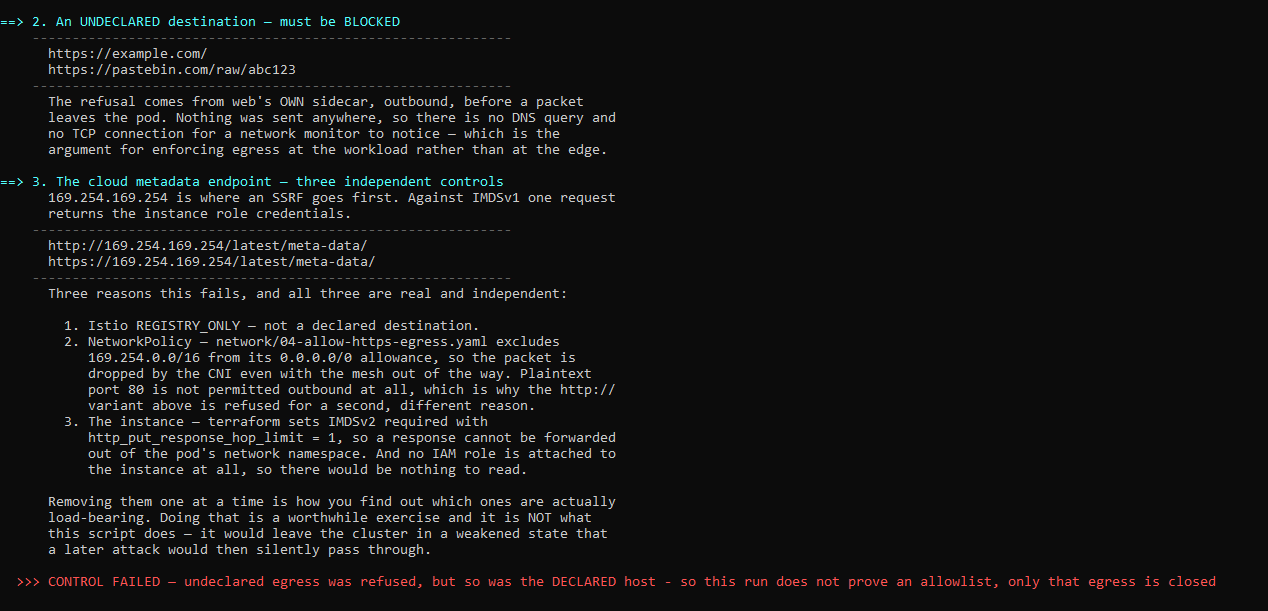
| 5 | Exfiltration to an undeclared host | 6 over 5 | Held | Declared host REACHED status=200; example.com and pastebin.com both BLOCKED |
| 6 | Manual edit of a live resource | 2 | Failed | ComparisonError: .status.terminatingReplicas: field not declared in schema |
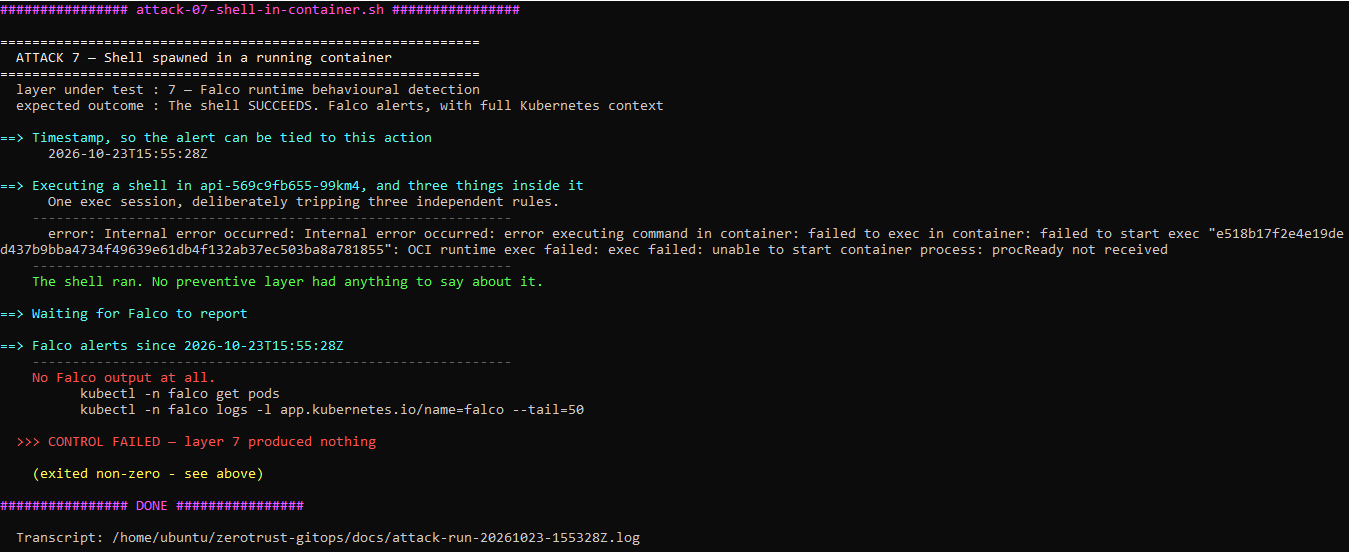
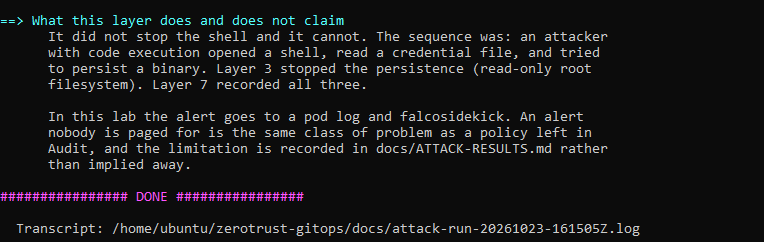
| 7 | Shell in a running container | 7 | Held | [Critical] Shell spawned in a governed namespace ns=zt-prod pod=api-… proc=sh |
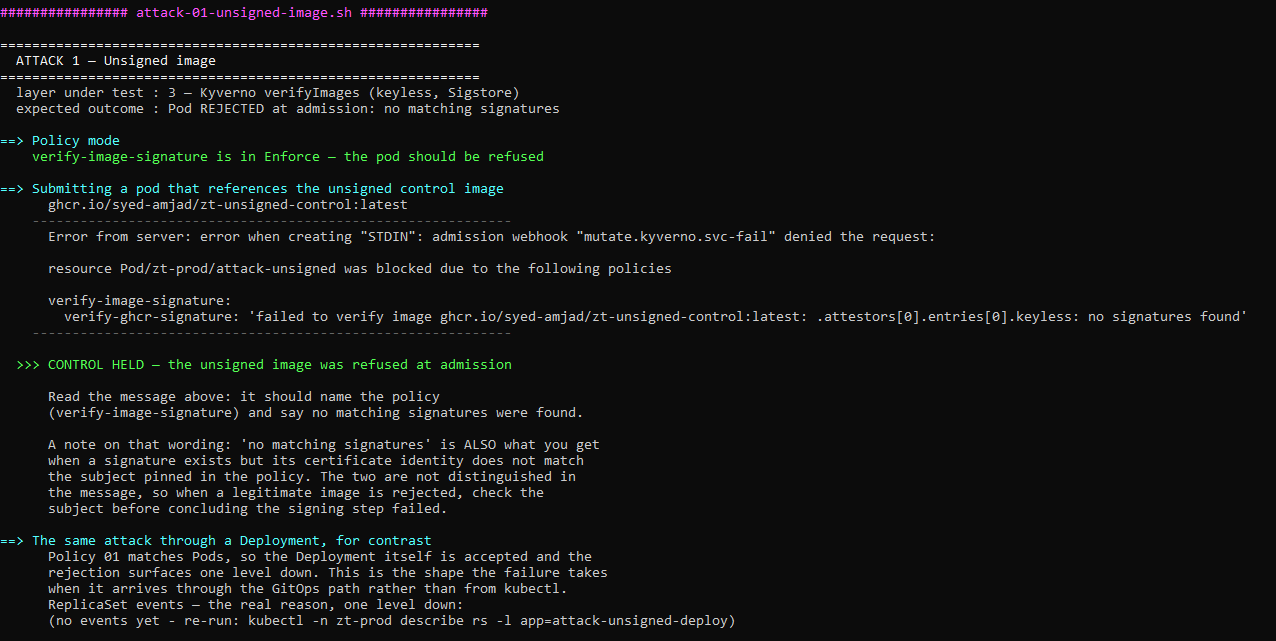
no matching signatures is what you get both when there is no signature and when a signature exists from the wrong identity — so a legitimate image rejected this way means checking the signing subject first.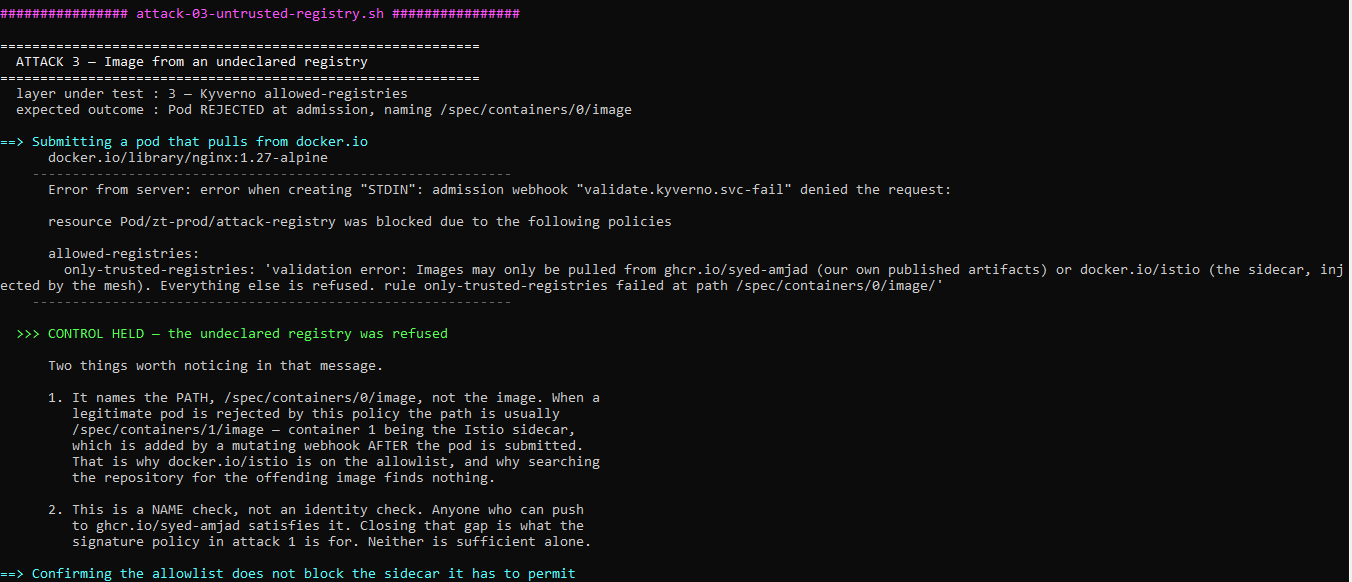
/spec/containers/1/image — the Istio sidecar, added by a mutating webhook after submission — which is why docker.io/istio is on the allowlist and why searching the repository for the offending image finds nothing.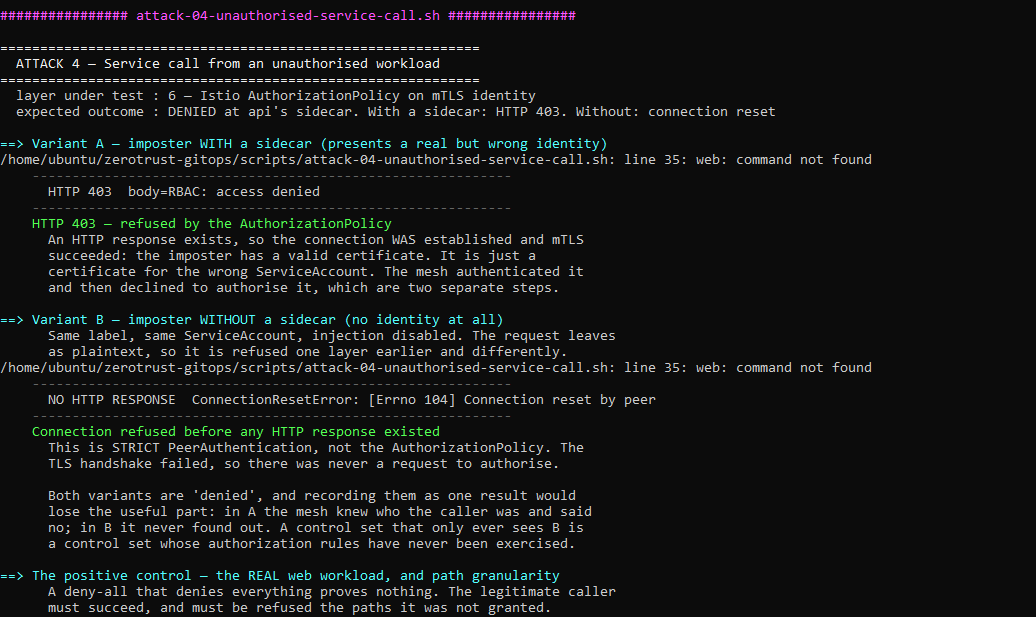
web: command not found lines are defect 12 below — cosmetic, and fixed.)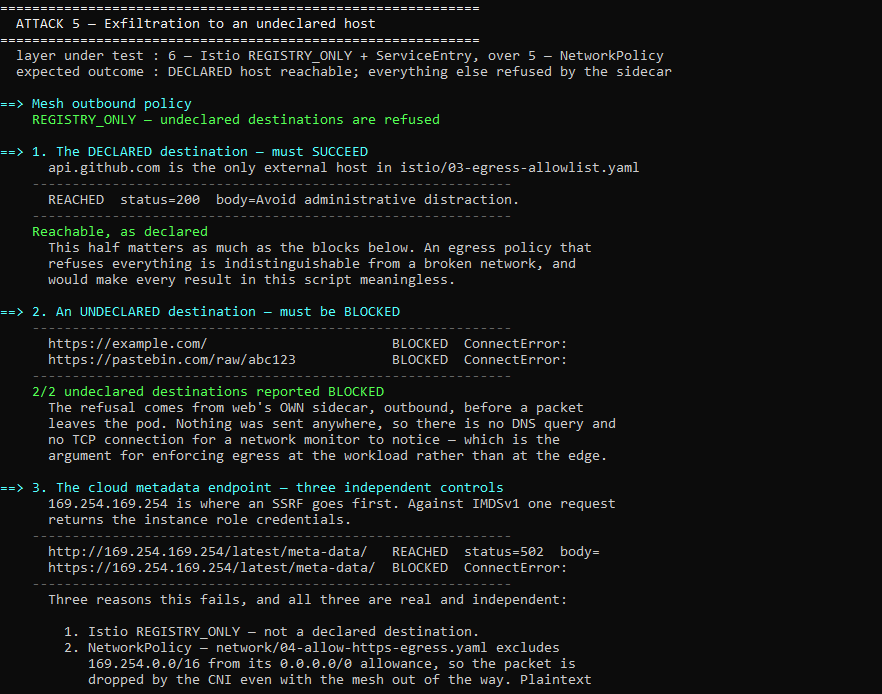
502 on plain-HTTP metadata is the sidecar's blackhole answering; nothing reached the instance.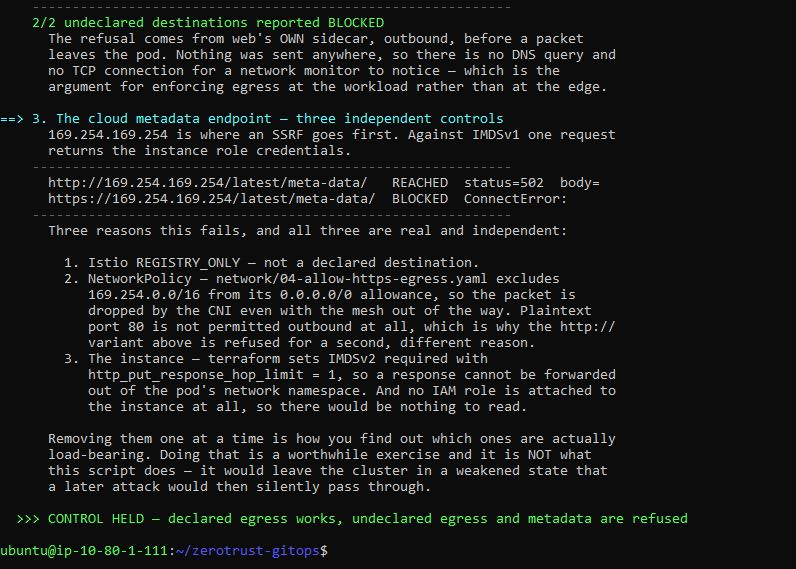
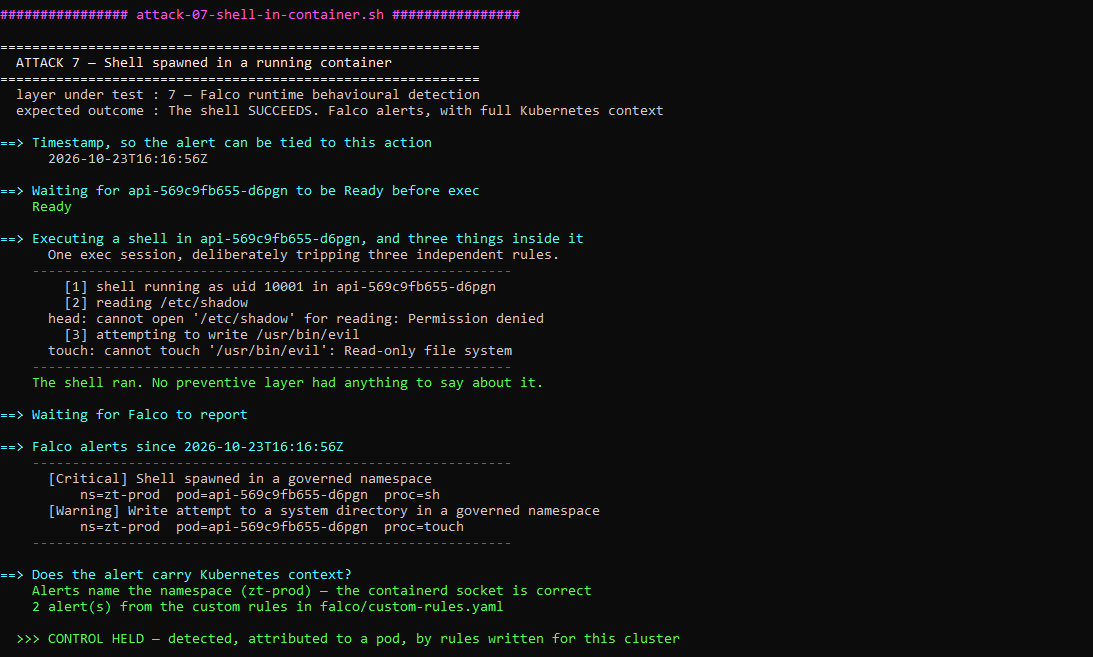
/etc/shadow is refused by file permissions and the write to /usr/bin by the read-only root filesystem: layer 3 stopped the persistence, layer 7 recorded it. The alert names the real namespace, ns=zt-prod — an alert reading <NA> would mean the default ruleset fired and the cluster-scoped rules did not.Audit before Enforce, run as two passes
Every Kyverno policy ships with validationFailureAction: Audit. The attacks were run twice — once in Audit, once in Enforce — and both transcripts kept, because the pair is the demonstration:
| Attack | Audit | Enforce |
|---|---|---|
| 1 unsigned image | pod/attack-unsigned created — violation recorded only | admission webhook "mutate.kyverno.svc-fail" denied the request |
| 2 privileged (PSA-off namespace) | pod/attack-priv created | admission webhook "validate.kyverno.svc-fail" denied the request |
| 3 untrusted registry | pod/attack-registry created | denied, naming /spec/containers/0/image |
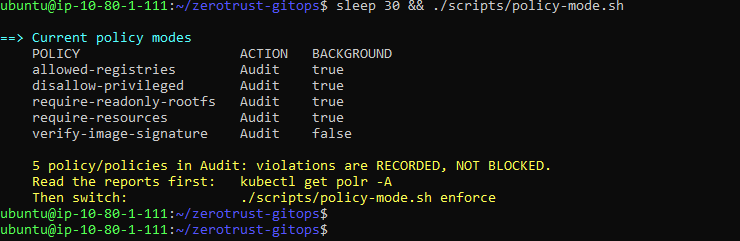
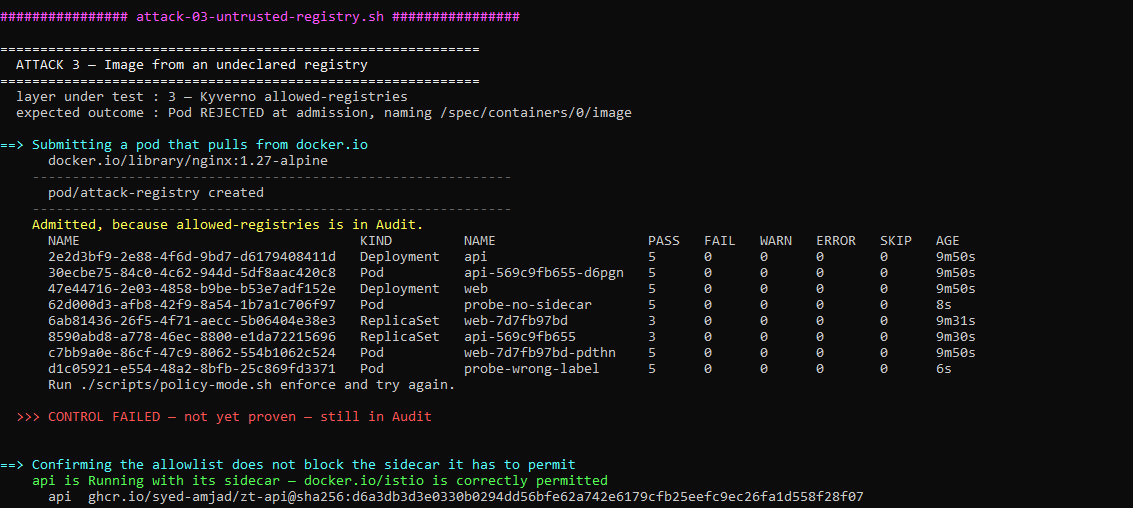
The switch to Enforce is a commit, not a kubectl patch — see the defects below for why that distinction turned out to be load-bearing.
Signature identity, verified by hand
The strongest claim here is that compromising the registry alone is not enough. A passing admission check cannot distinguish “the signature matched the pinned identity” from “my policy is looser than I think it is”, so cosign was run twice against the same digest — once with the correct identity, once with a wrong one from the same repository and branch.
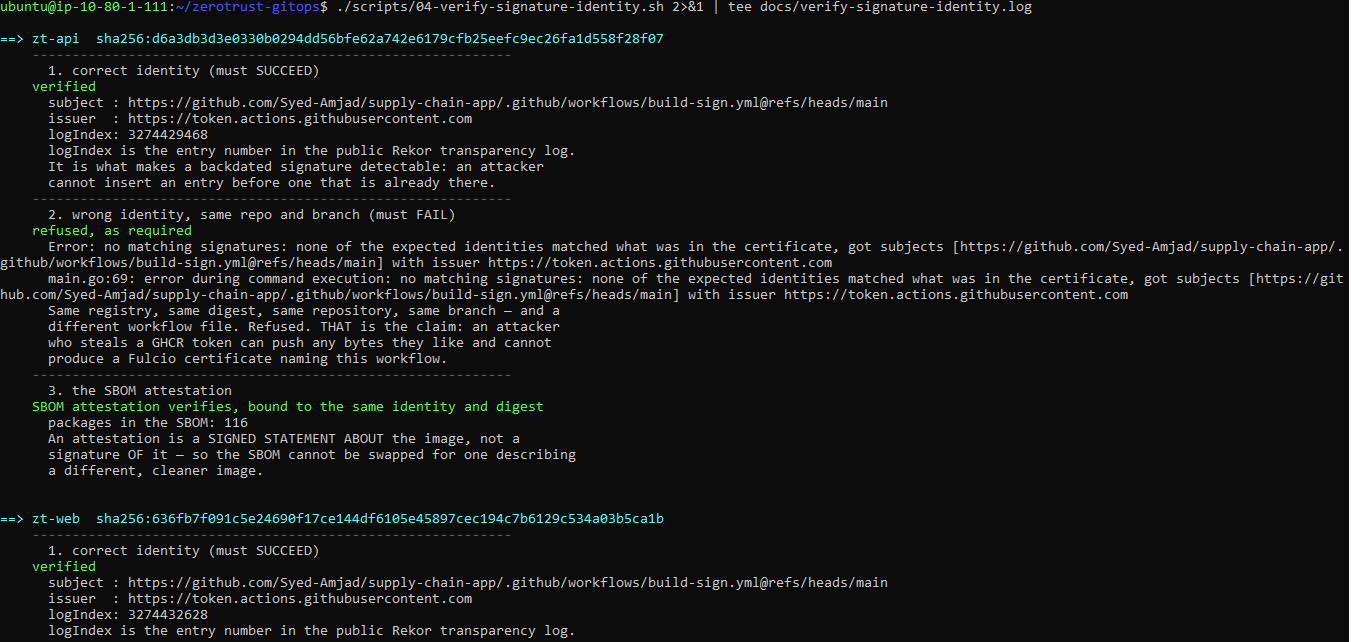
logIndex is the entry in the public Rekor log, which is what makes a backdated signature detectable.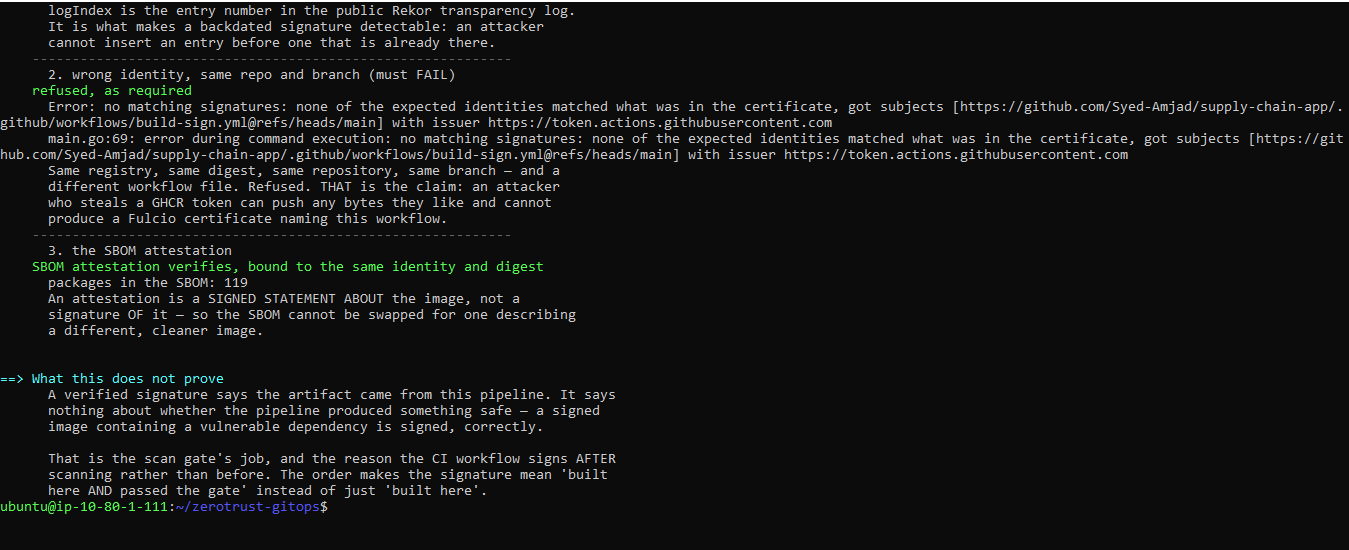
The one that failed, and why it is the most valuable result
Attack 6 scales a Deployment to 7 replicas by hand and watches for ArgoCD to revert it. Sixty seconds later it was still at 7.
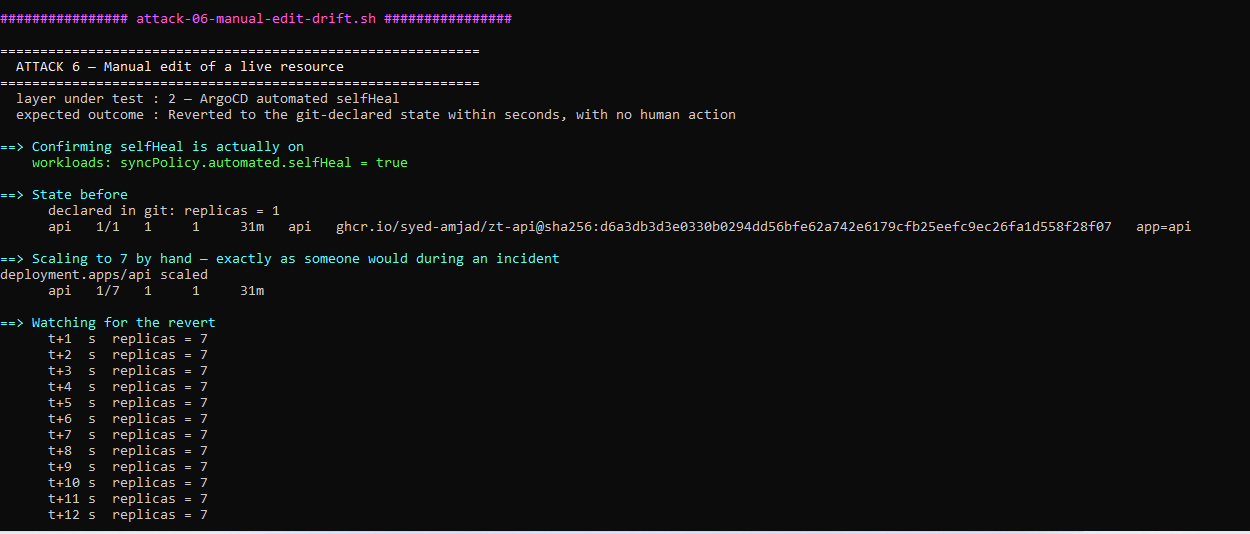
selfHeal = true confirmed first. Then the hand edit, and a revert that never comes.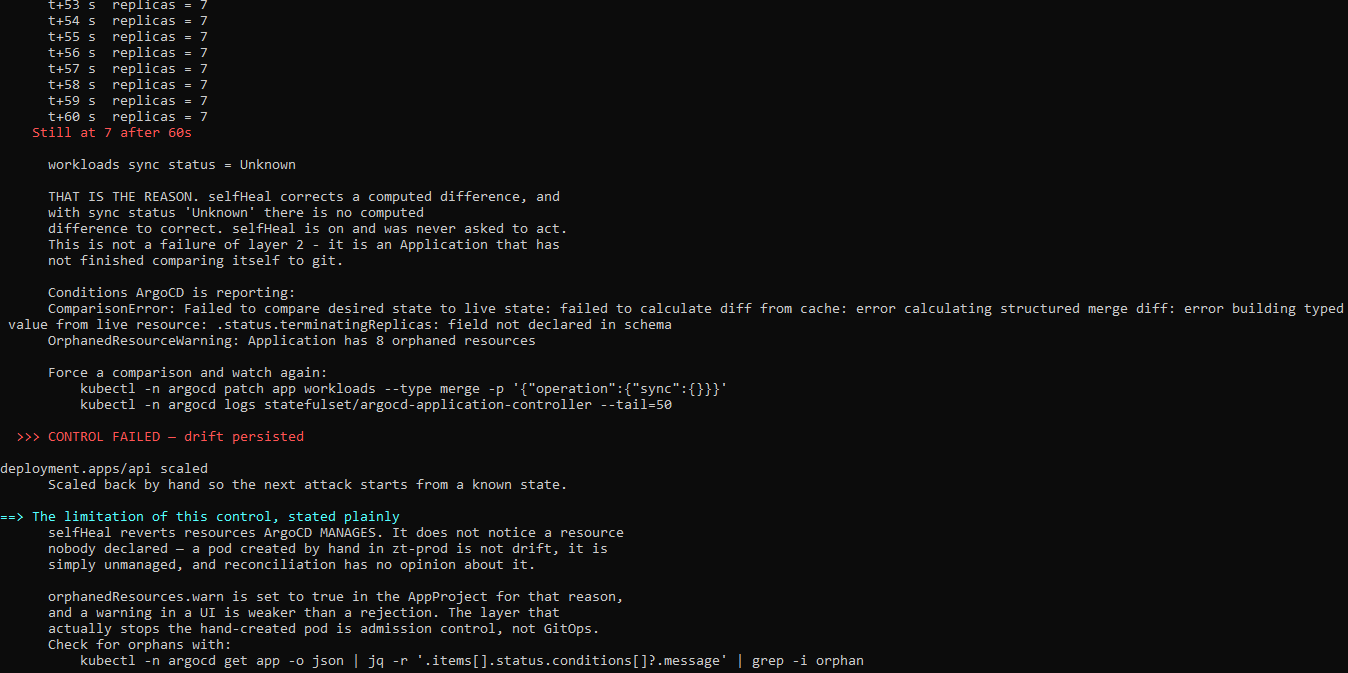
.status.terminatingReplicas: field not declared in schema.ArgoCD v2.13.2 did not recognise .status.terminatingReplicas, a Deployment status field present in the Kubernetes the cluster was running (k3s v1.36.5). Its structured-merge diff could not compute a difference. With no computed difference, selfHeal had nothing to correct — and never ran.
Everything on the dashboard said this was fine. The Application reported Healthy. syncPolicy.automated.selfHeal reported true. The only visible symptom was a sync status of Unknown, which reads like a transient.
Pinning the GitOps controller to a version older than the cluster silently disabled drift correction. Nothing alerted. The control that is supposed to notice unauthorised change had itself stopped working, and the mechanism that would report that is the same mechanism that was broken.
That is worth more than a seventh passing row. The whole premise of this project is that a control which reads as enabled may not be enabled; attack 6 is that premise happening to the project itself.
Defects found
Fifteen defects surfaced. Six were in the platform or its dependencies; nine were in my own tooling, and those are listed too, because a results table containing only the expected outcomes tells a reader the interesting rows were deleted.
In the platform and its dependencies
| # | Defect | How it presented |
|---|---|---|
| 1 | Falco values written against the chart 4.x schema. collectors.containerd.socket does not exist in chart 9.x. | The chart ships no values.schema.json, so Helm accepted the unknown key silently, exit 0. Found by rendering the chart and reading the output — both files looked correct. |
| 2 | kyverno.io/v1 ClusterPolicy deprecated as of Kyverno 1.19. | A warning on every run. Pinned rather than worked around: an unpinned install would eventually stop enforcing on a cluster whose manifests had not changed, and kubectl get clusterpolicy would still list all five. |
| 3 | starlette was never pinned. fastapi only declared a range, so both images shipped starlette 0.41.3 with three HIGH CVEs that had published fixes. | The very first CI run failed, on both matrix legs, at the Trivy gate. The tempting fix was to loosen the gate. The gate was satisfiable: --ignore-unfixed already suppresses unfixable base-image noise, and what got through named a fixed version for each finding. A floor is not a pin. |
| 4 | ArgoCD v2.13.2 against Kubernetes 1.36 — attack 6 above. | selfHeal silently stopped working while reporting true. |
| 5 | Kyverno’s webhook rewrites its own policies, so the Application is permanently OutOfSync while every policy is Ready and enforcing. | Cosmetic here, but with selfHeal: true it means ArgoCD and Kyverno each continuously “correcting” the other. |
| 6 | Istio 1.26 is past end of support. | Pinned deliberately. The pin is correct for reproducibility and simultaneously means running an unsupported version — a tension real in every version-pinning policy, and not resolvable by choosing one side. |
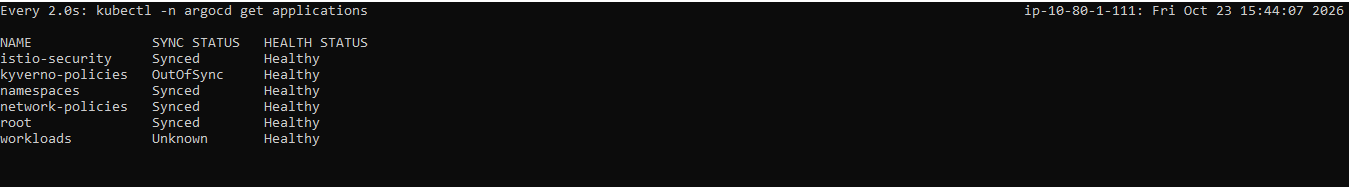
kyverno-policies is permanently OutOfSync while enforcing; workloads reads Unknown and Healthy — the state in which drift correction had silently stopped.In my own tooling — the honest half
Nine defects were mine, and they share one shape: a check that looked right and tested the wrong thing.
| # | Defect | Consequence |
|---|---|---|
| 7 | A hardcoded CNI plugin directory. The bootstrap passed cniBinDir=/var/lib/rancher/k3s/data/current/bin; k3s 1.36 resolves plugin names under /var/lib/rancher/k3s/data/cni. Both directories exist and both contain plugins. | It took out the whole node. istio-cni was correctly chained into 10-flannel.conflist but unreachable, so every CNI ADD failed — mesh and non-mesh pods alike. flannel allocates the address before the chain reaches istio-cni, so each kubelet retry leaked one host-local lease. After ~254 retries the node’s /24 was empty and every pod failed with no IP addresses available — an error naming flannel and pointing nowhere near the cause. Fourteen minutes from one wrong path to a dead node. |
| 8 | sudo grep -l PATTERN "$dir"/* — written twice, the second time inside the fix for the first. | The glob is expanded by the calling shell, which is unprivileged, and /var/lib/rancher/k3s is 0700 root. The glob matched nothing, the literal * reached grep, and 2>/dev/null hid why. Once it reported a missing istio-cni on a healthy node; once it aborted the bootstrap silently, because a failing pipeline inside a command substitution under set -euo pipefail exits with no message at all. |
| 9 | ls | grep istio to check the CNI config. | Istio’s default chained mode writes no file of its own — it edits the conflist already there. A correct install leaves no filename containing “istio”, so the gate fired on a healthy cluster. A gate that fires on a healthy cluster is one an operator learns to ignore. |
| 10 | kubectl wait --for=condition=Ready node --all straight after installing k3s. | wait --all does not wait for a resource to exist. With an empty set it exits 1 at once — error: no matching resources found — and the --timeout=180s on the same line actively misleads by implying it waited. |
| 11 | helm killed mid-install by an SSH drop. | Helm keeps release state in a Secret; a killed process strands it in pending-install, and the retry says “another operation is in progress”, which invites waiting. There is nothing to wait for. The runbook’s fault, not helm’s: it told the operator to run multi-minute silent installs in a bare SSH session. |
| 12 | Backticks in a YAML comment inside an unquoted heredoc. | Bash ran web as a command, printed web: command not found twice per run, and stripped the word from the comment. A YAML comment is still a shell expansion context under <<POD rather than <<'POD'. |
| 13 | attack-07 printed “The shell ran” unconditionally. | On the run where kubectl exec failed with procReady not received, it said so anyway — then reported “layer 7 produced nothing” as a Falco failure. Falco was right. Nothing had happened. The script turned its own bug into another component’s failure. |
| 14 | attack-05’s verdict was a hardcoded verdict 0, and its probe ended in 2>/dev/null. | The probe returned the empty string whenever kubectl exec failed, so every destination printed as a bare URL — and the script read that silence as “blocked”, then printed CONTROL HELD beneath a line saying the declared host was unreachable. An absent result is not a block. |
| 15 | lab-down.sh printed the AWS account instead of asserting it. | Run against the wrong profile, terraform destroy does not error — it is told the resources do not exist, concludes they were already deleted, and removes them from state. The script then verified “against AWS” in that same wrong account, found nothing, and reported “Clean. Nothing is billing.” Both halves of the safety net failed in the same direction, leaving a t3.large running with an empty state file. |
Every one of these is now fixed, and each fix was verified by reproducing the failure first: a 0700 directory for the glob, a stubbed kubectl returning no nodes, a simulated chained conflist, five fake k3s layouts for the path discovery, six helm release states, and a fake state file in the wrong account.
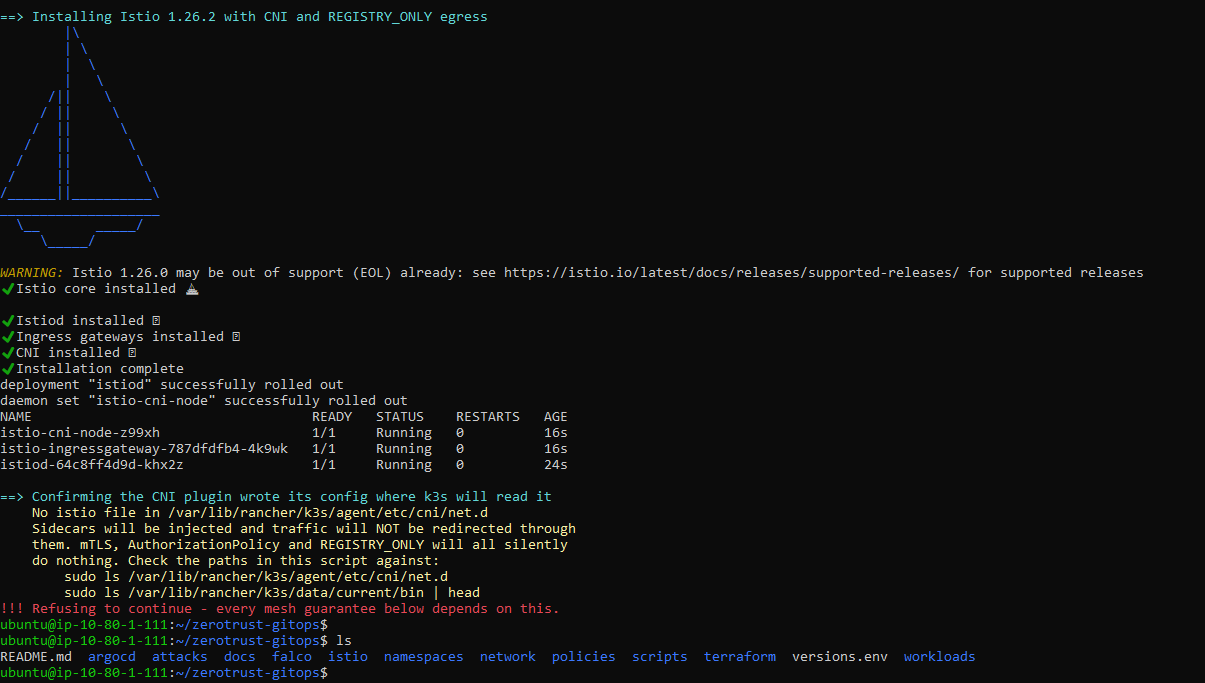
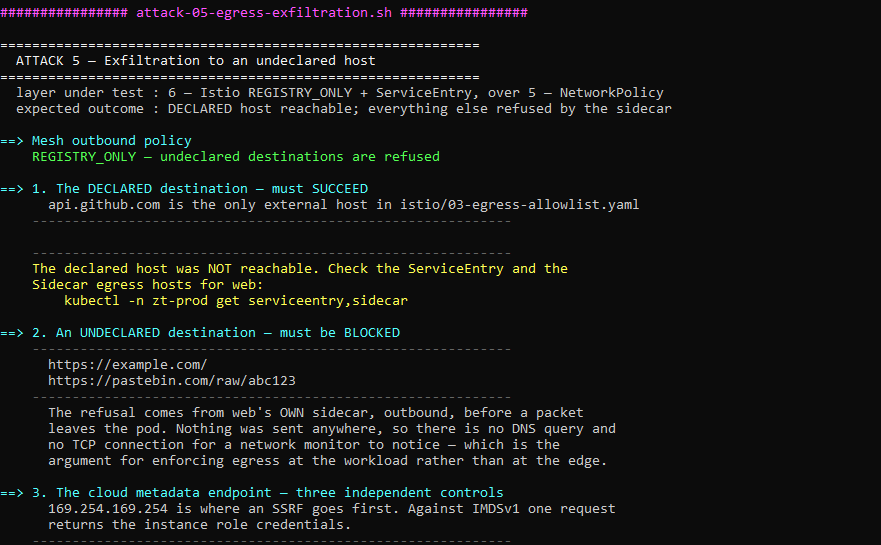
2>/dev/null hid it.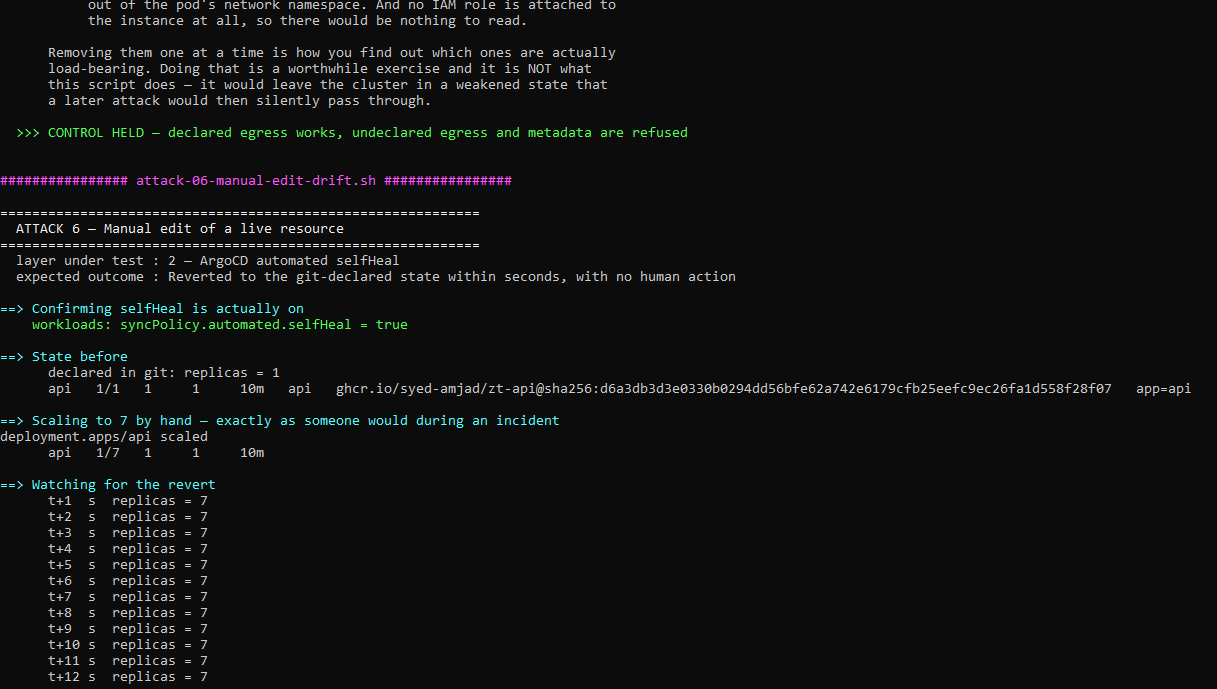
Defect 15 is the one I would want a reader to take away. A teardown script that prints the account rather than checking it is worse than no teardown script, because it is trusted. It now reads the owning account out of the state file’s resource ARNs, compares it to the caller, and refuses on a mismatch.
What this platform does not claim
These limitations are in the repository too.
- Falco detects; it does not prevent. Attack 7 succeeded by design. In this lab the alert goes to a pod log and falcosidekick. An alert nobody is paged for is the same class of problem as a policy left in Audit.
- Egress filtering is hostname-level, not path-level. For a TLS destination the mesh matches on SNI and does not terminate the connection. Path-level filtering of an external HTTPS call would mean intercepting your own TLS, with the certificate-distribution problem that brings. Hostname-from-a-named-workload is the honest description — and it still defeats the attack: exfiltration needs a destination, and an attacker cannot add one without write access to the repository.
selfHealreverts resources ArgoCD manages. A pod created by hand is not drift — it is unmanaged, and reconciliation has no opinion about it. The layer that stops the hand-created pod is admission control, not GitOps.orphanedResources.warnis set for that reason, and a warning in a UI is weaker than a rejection.- An allowlist is a name check, not an identity check. Anyone who can push to
ghcr.io/syed-amjadsatisfies the registry policy. Closing that gap is what the signature policy is for. Neither is sufficient alone, which is the argument for having both. - Single node. Everything runs on one
t3.largeat about $0.083 an hour. That is enough to demonstrate every control and not enough to say anything about behaviour under scale or node failure.
Stack and cost
| Component | Version | Why pinned |
|---|---|---|
| k3s | v1.36.5+k3s1 | The NetworkPolicy controller is on by default — layer 5 depends on it entirely |
| Istio | 1.26.2 | CNI plugin mode: restricted PSA forbids the NET_ADMIN an init container would need |
| Kyverno | chart 3.9.1 | verifyImages is the legacy path as of 1.14; the install asserts the CRD still carries the field |
| Falco | chart 9.2.0 | Driver load and the k3s containerd socket are both asserted, not assumed |
| ArgoCD | v2.13.2 | Too old for this cluster — see defect 4 |
| cosign | v2.4.1 | Keyless, Fulcio + Rekor |
| Terraform | AWS provider 5.x | IMDSv2 required, http_put_response_hop_limit = 1, no IAM role attached |
Total AWS spend for the build: one t3.large for roughly six hours, plus a 40 GB gp3 root volume — under $1. The instance is destroyed between sessions, and the whole platform rebuilds from git in about an hour.
Repositories
| zerotrust-gitops | Namespaces, five Kyverno ClusterPolicies, NetworkPolicies, Istio security objects, workloads, ArgoCD Applications in sync waves 0–4, Terraform, the attack scripts — and both full transcripts, attack-run-audit.log and attack-run-enforce.log, under docs/ |
| supply-chain-app | Two FastAPI services, non-root on numeric UID 10001 with a read-only root filesystem. CI builds, scans with Trivy, fails on fixable HIGH or CRITICAL, signs with cosign keyless, generates an SBOM attestation, and writes the resulting digest into the GitOps repository — never a tag |
CI has no kubeconfig and no cluster credentials. A compromised application pipeline can push a bad image; it cannot rewrite cluster configuration directly — and Kyverno then refuses the bad image at admission, which is the point of the split.
Every quoted message on this page is in one of the two transcripts, in context — including the ones that record my own mistakes. The results were filled in from the transcript while it was in front of me, not written from memory afterwards.
Relationship to my production work
This is the same default-deny with an explicit allowlist architecture I ran in production for host firewalls across a Linux fleet — applied here at seven layers, from the CI pipeline down to the kernel.
The firewall enforces at L3/L4 on source address and port. Istio enforces at L7 on cryptographically verified workload identity. Same design, different layer — and the same lesson keeps arriving from both directions: the most dangerous control is the one that reports healthy while doing nothing.
The build, start to finish
Expand the walkthrough — offline tests to the Audit pass
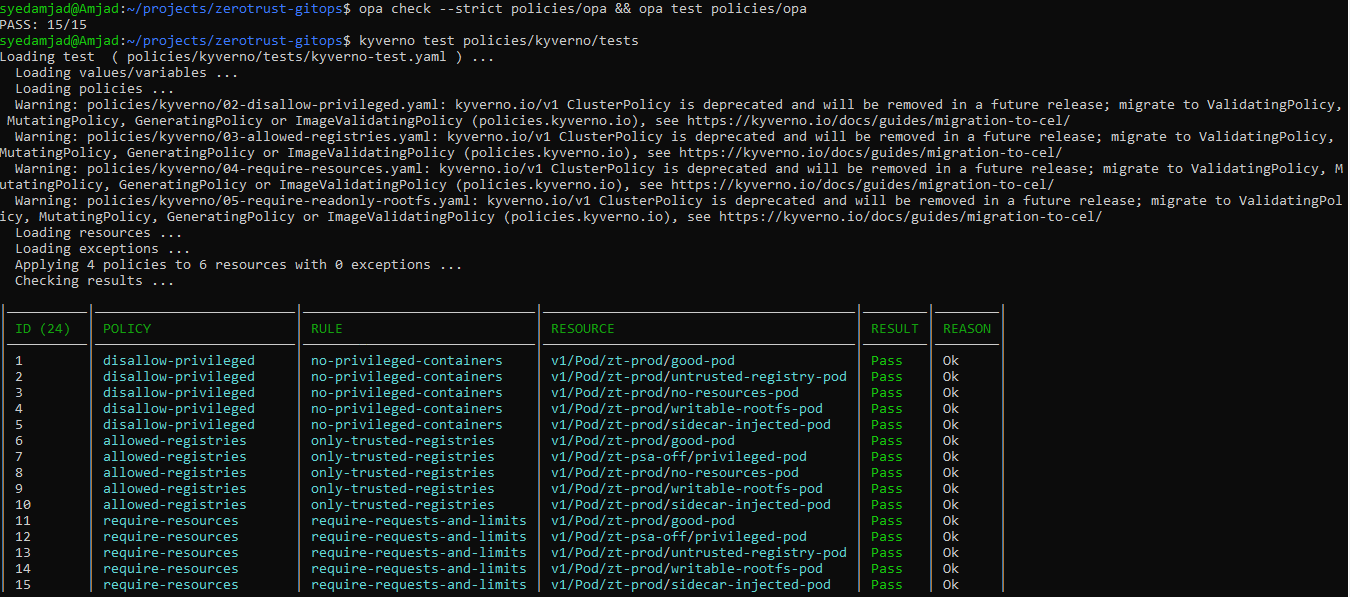
1 · Policies tested before any cluster exists
2 · The first verification, in Audit
3 · The attacks in Audit — admitted and recorded
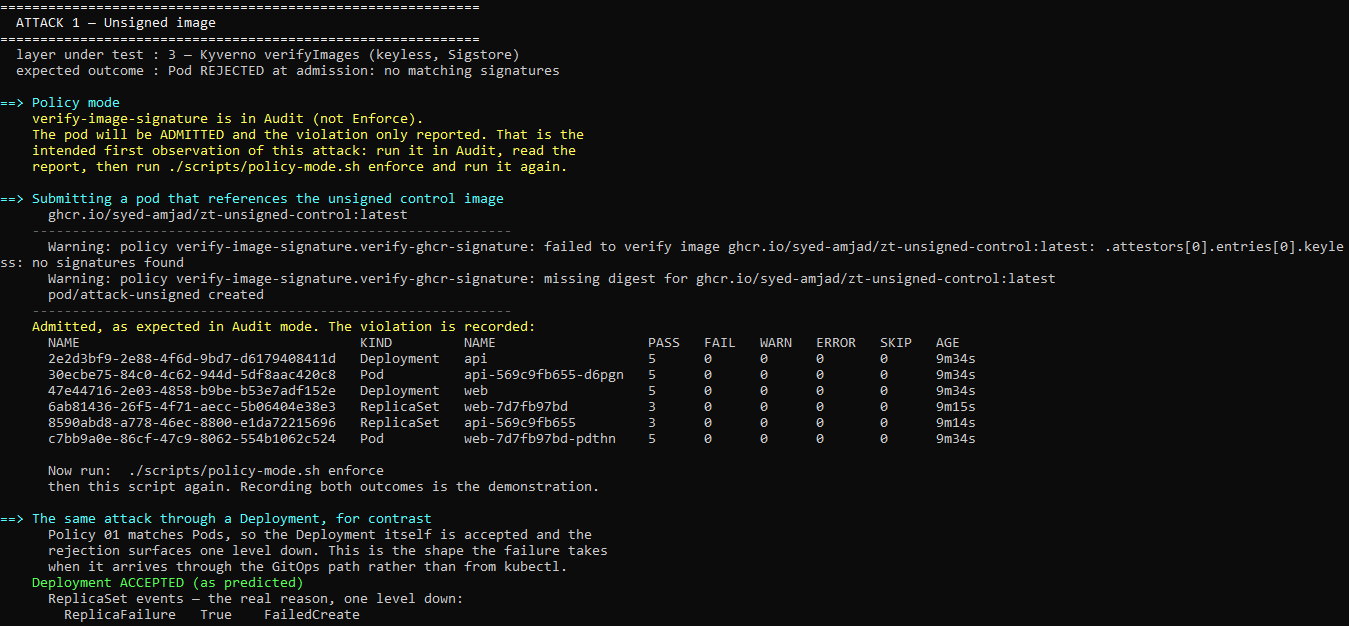
kubectl.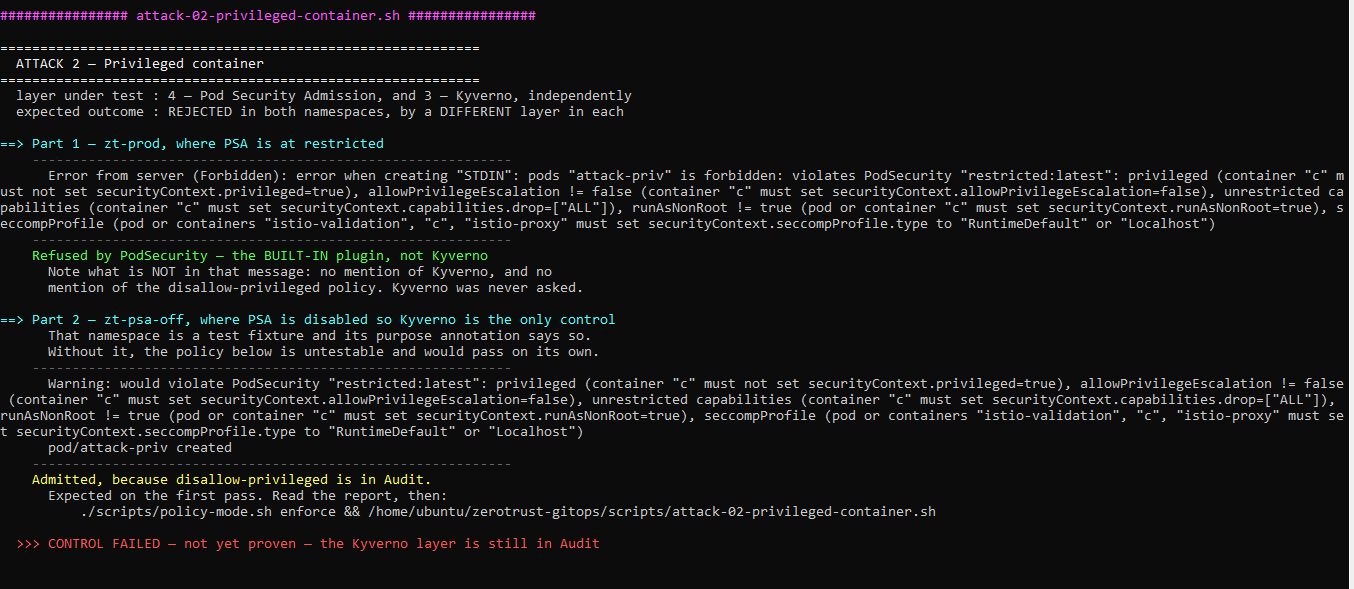
zt-prod; in the PSA-off fixture the pod is admitted, and the script refuses to call that a pass.